AnyToSpeech vs MusicLM
In the clash of AnyToSpeech vs MusicLM, which AI Audio Generation tool emerges victorious? We assess reviews, pricing, alternatives, features, upvotes, and more.
When we put AnyToSpeech and MusicLM head to head, which one emerges as the victor?
Let's take a closer look at AnyToSpeech and MusicLM, both of which are AI-driven audio generation tools, and see what sets them apart. There's no clear winner in terms of upvotes, as both tools have received the same number. Your vote matters! Help us decide the winner among aitools.fyi users by casting your vote.
Think we got it wrong? Cast your vote and show us who's boss!
AnyToSpeech

What is AnyToSpeech?
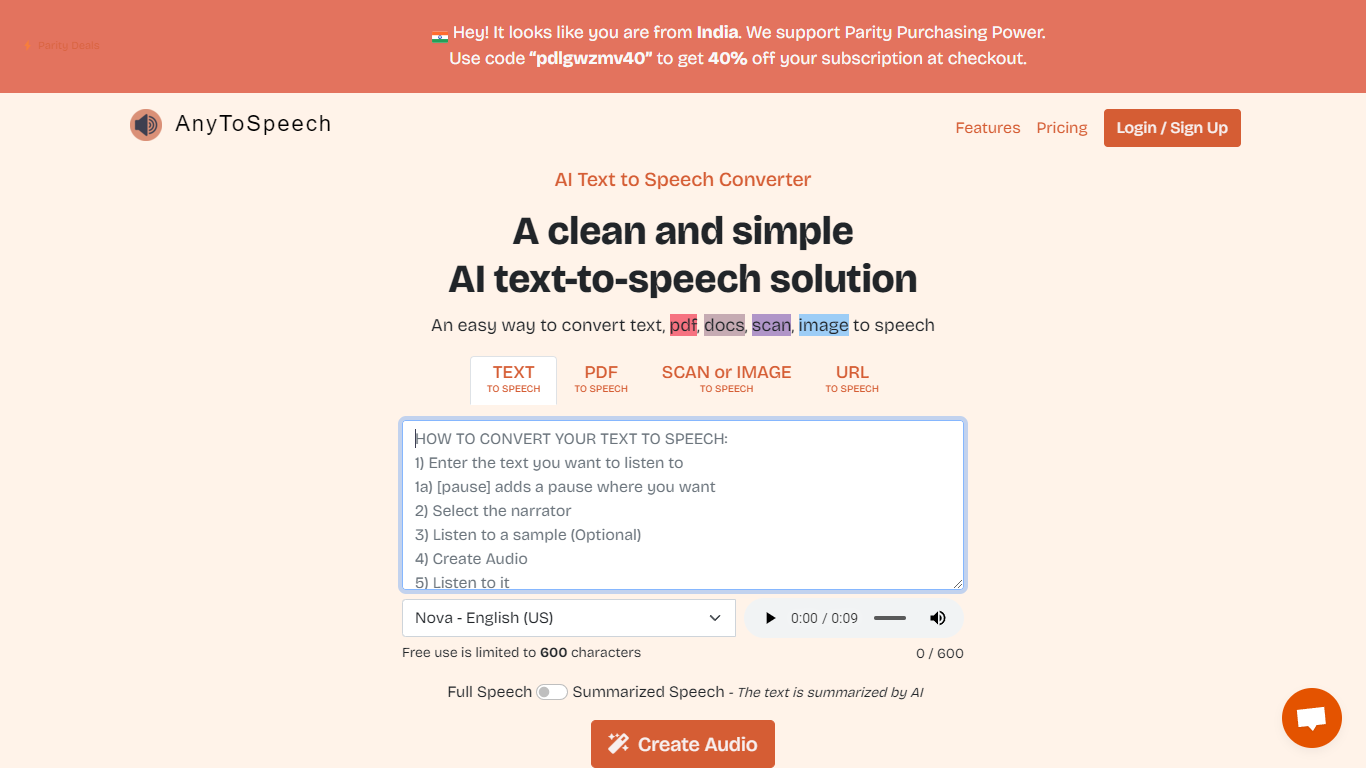
AnyToSpeech is an online text-to-speech platform that turns written content into spoken audio. Paste plain text, upload PDFs, drop in URLs, or pull text from images and get MP3 files back with natural-sounding voices.
The platform goes well beyond basic TTS. You can build PDF and document audiobooks, narrate webpages, run speech-to-text transcription, clone your voice from short recordings, and generate two-speaker podcast episodes from a topic brief or script. PDF conversion skips page numbers, footnotes, and table-of-contents sections so the listening flow stays clean.
AnyToSpeech offers hundreds of voice options across many languages and accents, plus a large set of free analysis tools for pronunciation, accent detection, and voice scoring. Mobile apps are available on Google Play and the Apple App Store.
It fits creators, authors, educators, and anyone who wants to listen instead of read.
MusicLM
What is MusicLM?
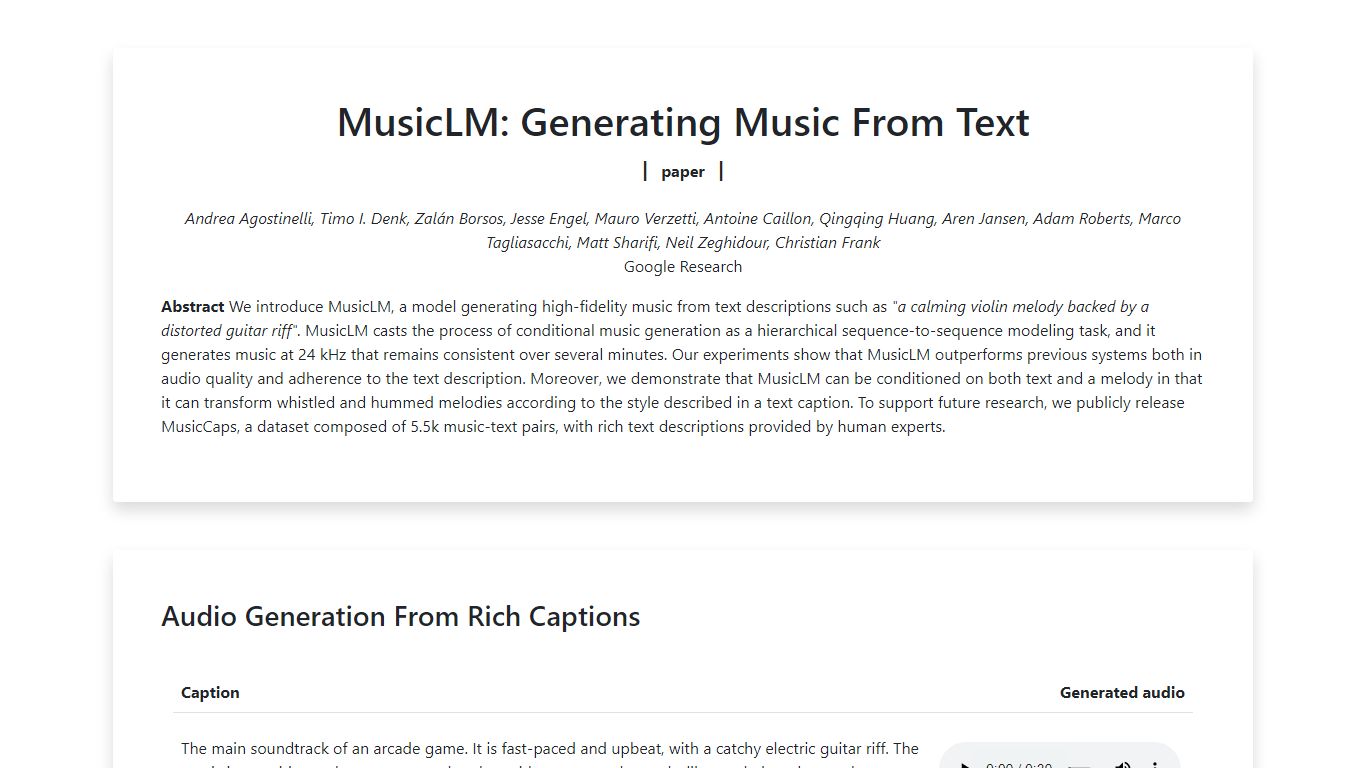
MusicLM is a Google Research audio generation model that creates music from text captions at 24 kHz. The public examples page hosts sample clips for prompts like arcade soundtracks, reggaeton-EDM fusions, and relaxing jazz, plus longer story-mode generations that shift styles across timed segments. Google released the MusicCaps dataset of 5,500 music-text pairs alongside the paper.
Unlike consumer apps that ship one prompt box, MusicLM was published as a research demo with pre-generated samples rather than a login product. Its headline trick is joint text-and-melody conditioning: you can hum or whistle a tune and have the model re-render it in a new genre described in text. Story mode chains multiple captions so the music evolves across sections.
MusicLM matters as the research foundation behind Google's later Lyria music models, but this page is for listening to published examples, not creating new tracks interactively. Researchers and musicians study it for long-form consistency, painting-to-music conditioning, and melody transfer results documented in the 2023 paper.
AnyToSpeech Upvotes
MusicLM Upvotes
AnyToSpeech Top Features
Paste text or upload PDFs, DOCX, and URLs, then download polished MP3 audio with adjustable speaking rate
Clone your voice from three short recordings in about 30 seconds and use it across every conversion tool
Generate two-speaker podcast episodes from a topic or script, complete with intro music and a spoken title
Upload audio or video files for transcription you can translate to 100+ languages, with 50 free minutes monthly
Choose from hundreds of voices across 24+ interface languages, including region-specific accents worldwide
MusicLM Top Features
Generates music at 24 kHz from rich text captions
Story mode chains multiple text prompts across timed segments
Text-and-melody conditioning transforms hummed or whistled tunes into new styles
Painting caption conditioning pairs artwork descriptions with generated audio
Long-generation examples cover melodic techno, swing, and relaxing jazz
MusicCaps dataset includes 5,500 expert-written music-text pairs
AnyToSpeech Category
- Audio Generation
MusicLM Category
- Audio Generation
AnyToSpeech Pricing Type
- Freemium
MusicLM Pricing Type
- Free