audyo.ai vs VALL-E
Explore the showdown between audyo.ai vs VALL-E and find out which AI Audio Generation tool wins. We analyze upvotes, features, reviews, pricing, alternatives, and more.
When comparing audyo.ai and VALL-E, which one rises above the other?
When we contrast audyo.ai with VALL-E, both of which are exceptional AI-operated audio generation tools, and place them side by side, we can spot several crucial similarities and divergences. audyo.ai is the clear winner in terms of upvotes. audyo.ai has garnered 6 upvotes, and VALL-E has garnered 5 upvotes.
Don't agree with the result? Cast your vote and be a part of the decision-making process!
audyo.ai

What is audyo.ai?
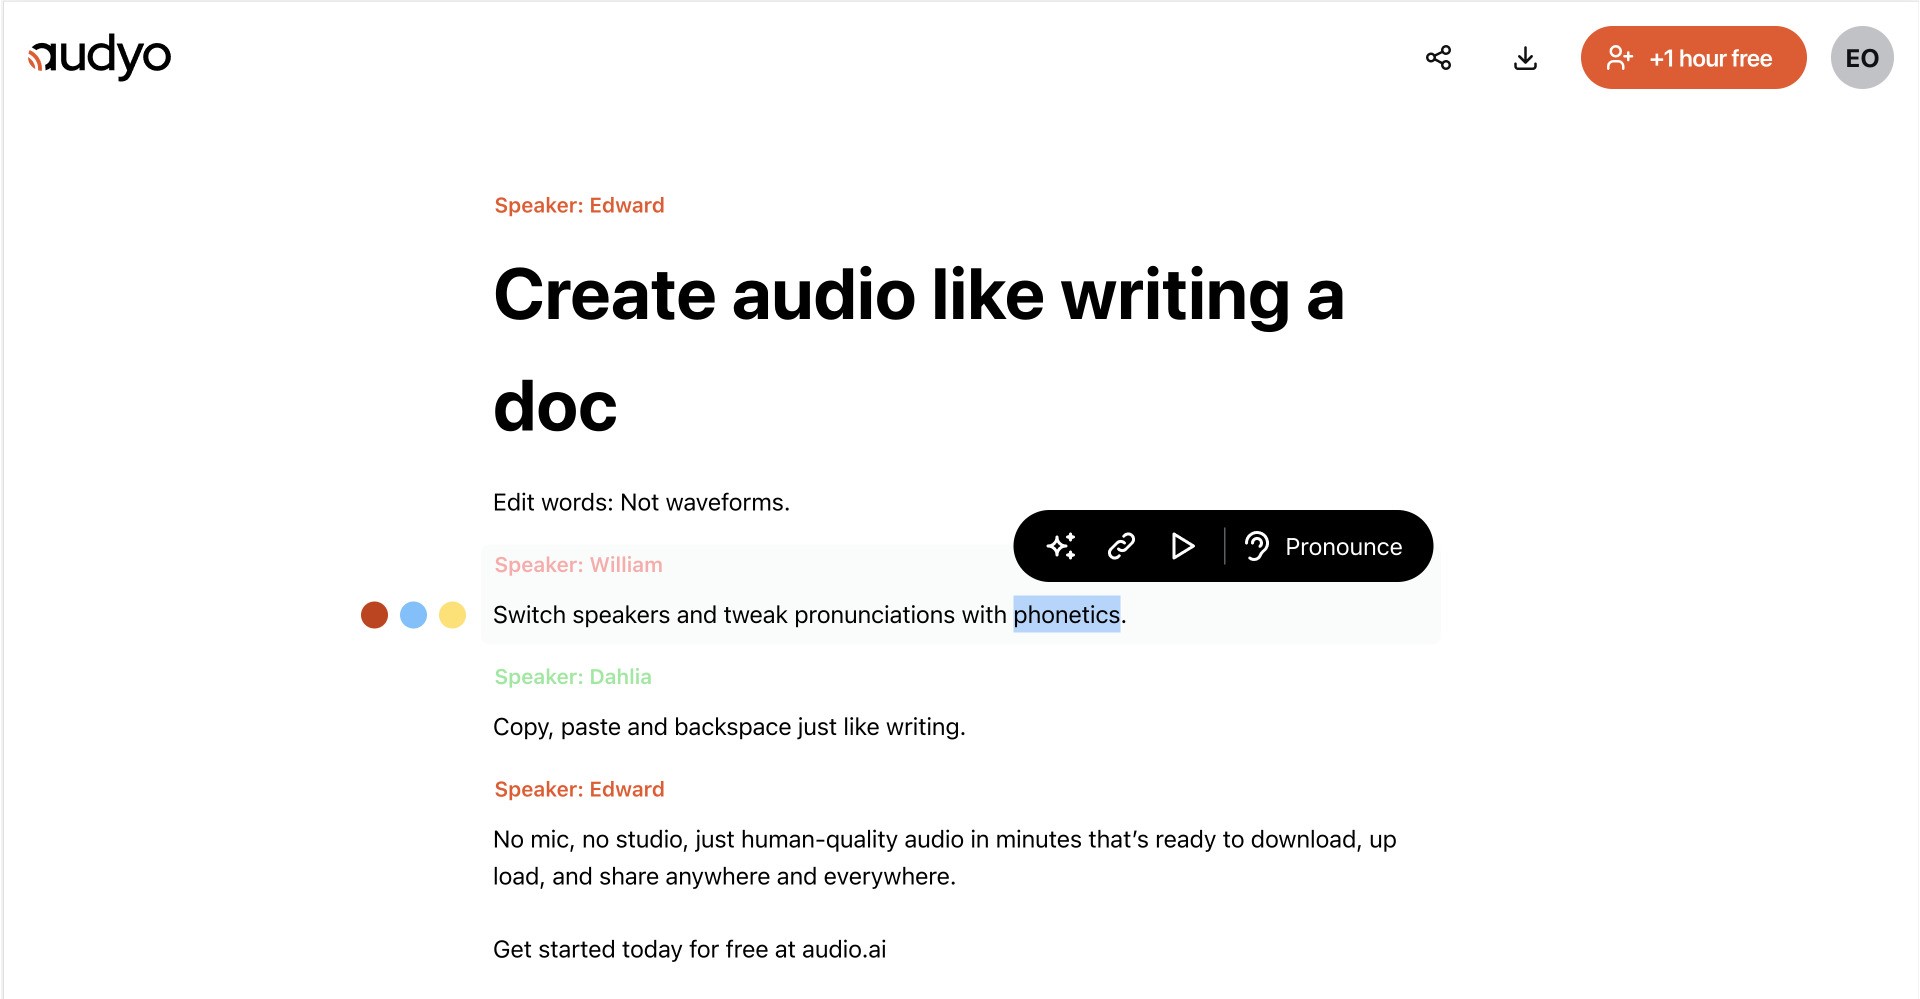
Audyo converts typed text into downloadable speech through a document-style editor. You write or paste a script, choose from 100+ voices across languages and accents, and export audio for videos, podcasts, presentations, and other projects without recording in a studio.
Most audio tools make you trim waveforms and re-record when a line changes. Audyo keeps the script as the source of truth, so you revise text, swap speakers, and regenerate audio without touching a timeline. That text-first workflow fits creators who treat narration like a draft, not a one-take studio session.
You can build multi-voice conversations, mix languages in one project, set custom pronunciations with phonetics, format scripts with Markdown, and use the built-in assistant to refine copy before generating audio. Audyo lists support for English, French, Spanish, German, Italian, Brazilian Portuguese, Japanese, Korean, Chinese, Hindi, Arabic, Turkish, and Russian, with use cases such as voice-overs, podcasts, audiobooks, and video narration.
VALL-E
What is VALL-E?
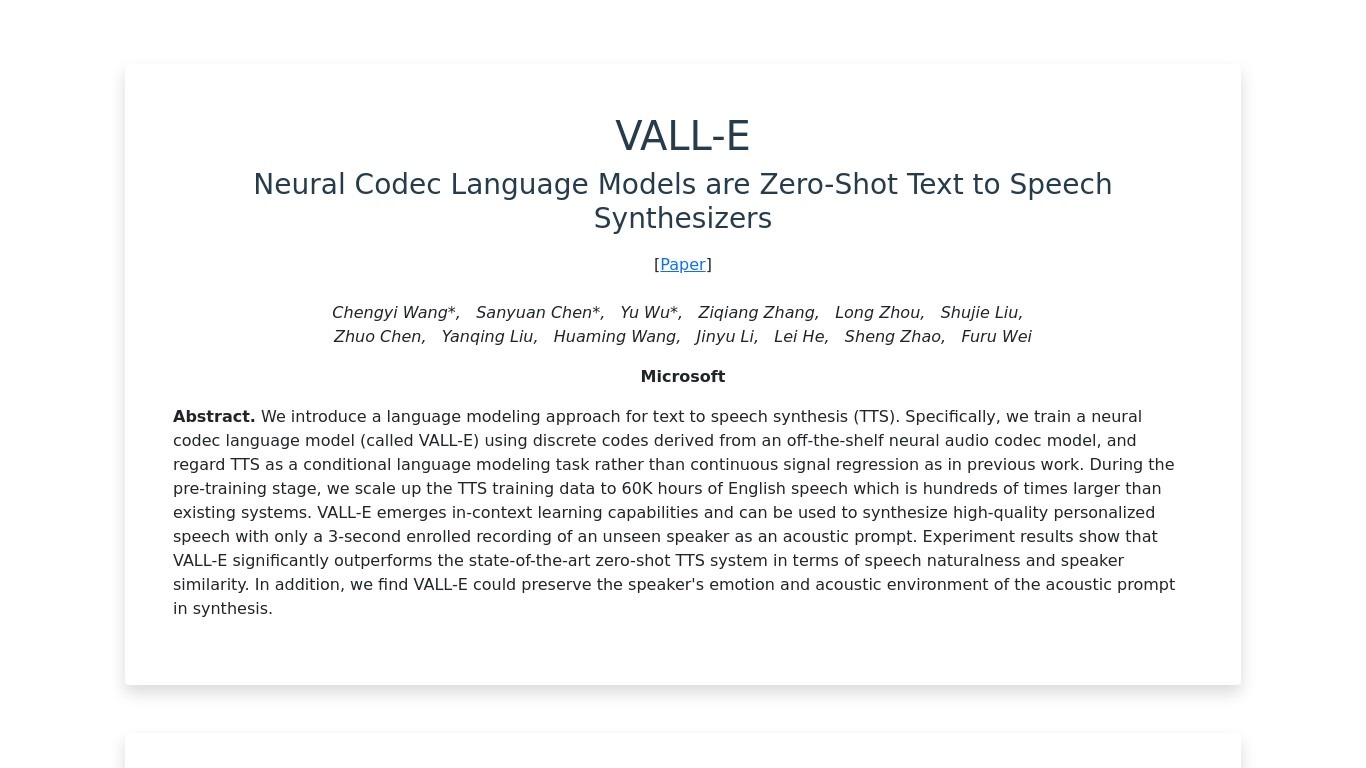
VALL-E is a Microsoft Research text-to-speech model that clones a speaker's voice from a short audio clip and generates new speech from text. It belongs to the audio generation category because it synthesizes natural speech rather than editing existing recordings. The project page hosts sample audio for the original VALL-E model and later variants in the same research family.
Most TTS systems regress continuous waveforms or mel-spectrograms directly. VALL-E instead treats speech as a conditional language modeling task over discrete codes from a neural audio codec. Microsoft trained it on about 60,000 hours of English speech, far larger than typical TTS datasets. A 3-second enrolled recording of an unseen speaker is enough to drive zero-shot synthesis, and the model can keep the emotion and room tone present in that prompt.
The VALL-E family grew beyond the first paper. VALL-E X handles cross-lingual zero-shot TTS, VALL-E R adds phoneme monotonic alignment for more stable speech generation, and VALL-E 2 pairs repetition-aware sampling with grouped code modeling to reach human parity on LibriSpeech and VCTK benchmarks. Related lines like MELLE, FELLE, and PALLE explore continuous mel tokens and hybrid autoregressive plus parallel decoding.
Researchers, speech engineers, and curious listeners use VALL-E to hear what large-scale codec language models can do before building their own pipelines. The public samples are research demos, not a hosted API you can plug into a product without separate licensing and ethics review.
audyo.ai Upvotes
VALL-E Upvotes
audyo.ai Top Features
Choose from 100+ voices across 13 supported languages and regional accents
Edit scripts like a document instead of trimming audio waveforms
Generate up to 15 minutes of audio on the free plan before upgrading
Swap speakers quickly to build multi-voice conversations
Buy one-time audio hour packs from $3 with no subscription required
Export finished MP3 audio for videos, podcasts, and presentations
VALL-E Top Features
Clones an unseen speaker from a 3-second enrolled audio prompt
Pre-trained on about 60,000 hours of English speech data
VALL-E 2 reports human parity on LibriSpeech and VCTK zero-shot benchmarks
Preserves speaker emotion and acoustic environment from the prompt clip
VALL-E X extends zero-shot synthesis to cross-lingual scenarios
Sample pages cover seven model lines including MELLE, FELLE, and PALLE
audyo.ai Category
- Audio Generation
VALL-E Category
- Audio Generation
audyo.ai Pricing Type
- Freemium
VALL-E Pricing Type
- Free