FineShare FineVoice vs MusicLM
In the clash of FineShare FineVoice vs MusicLM, which AI Audio Generation tool emerges victorious? We assess reviews, pricing, alternatives, features, upvotes, and more.
When we put FineShare FineVoice and MusicLM head to head, which one emerges as the victor?
Let's take a closer look at FineShare FineVoice and MusicLM, both of which are AI-driven audio generation tools, and see what sets them apart. Both tools have received the same number of upvotes from aitools.fyi users. Your vote matters! Help us decide the winner among aitools.fyi users by casting your vote.
Does the result make you go "hmm"? Cast your vote and turn that frown upside down!
FineShare FineVoice

What is FineShare FineVoice?
FineShare FineVoice is a browser-based AI audio studio for text-to-speech, voice changing, cloning, and sound design. You can generate narration from scripts, swap voices in recordings, design custom voices from text prompts, and create royalty-free sound effects or background music without opening separate apps.
Most voice generators focus on narration alone. FineVoice bundles speech-to-text, voice enhancement, lip sync, talking photos, and podcast generation in one workspace, plus a linked VoiceTrans desktop app with 1,000+ real-time voice models for games and chat. Video voiceover export and full video localization are still marked Coming Soon, so it fits audio-first creators more than teams that need finished video exports today.
YouTube creators, podcasters, educators, marketers, and developers use FineVoice for multilingual voiceovers, character acting, and API-driven apps. The marketing site advertises no sign-up for core online trials, with paid tiers that raise monthly character quotas, clone slots, and speech-to-text minutes.
MusicLM
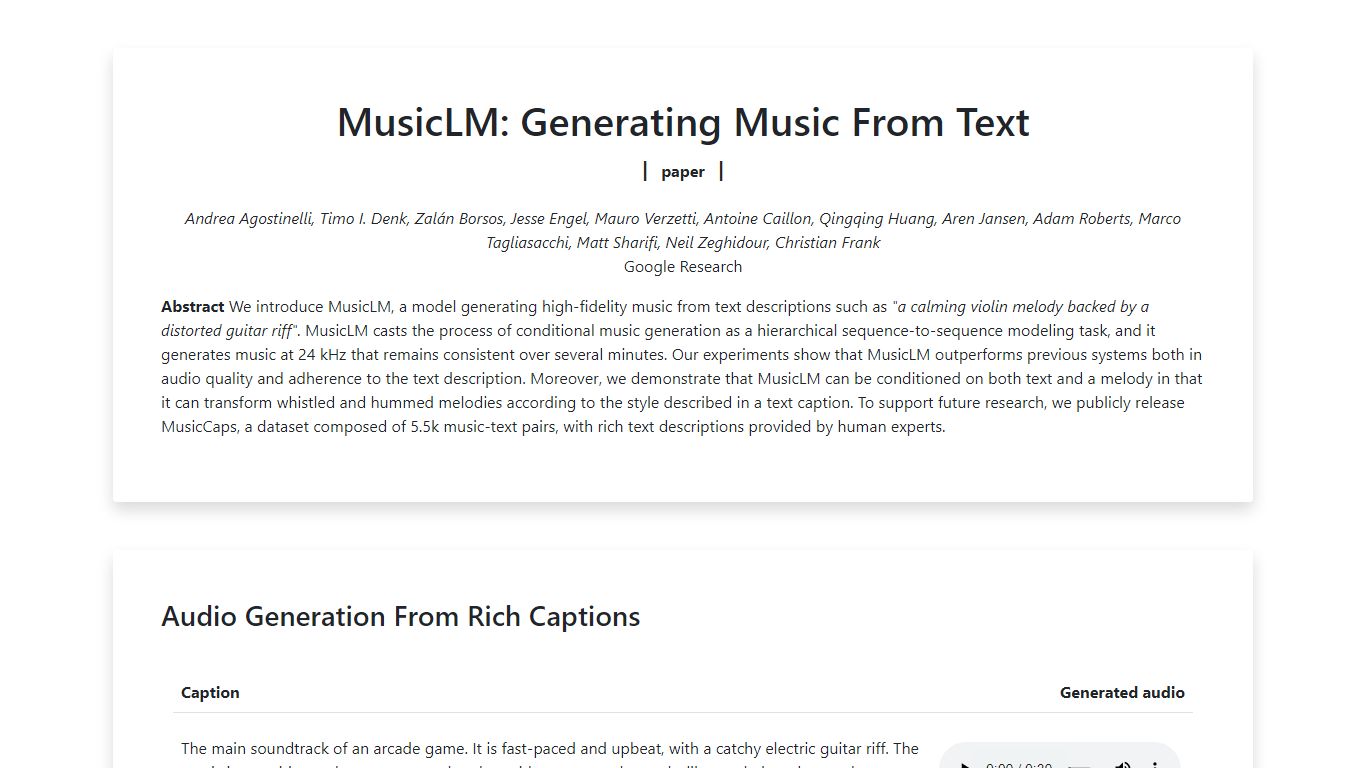
What is MusicLM?
MusicLM is a Google Research audio generation model that creates music from text captions at 24 kHz. The public examples page hosts sample clips for prompts like arcade soundtracks, reggaeton-EDM fusions, and relaxing jazz, plus longer story-mode generations that shift styles across timed segments. Google released the MusicCaps dataset of 5,500 music-text pairs alongside the paper.
Unlike consumer apps that ship one prompt box, MusicLM was published as a research demo with pre-generated samples rather than a login product. Its headline trick is joint text-and-melody conditioning: you can hum or whistle a tune and have the model re-render it in a new genre described in text. Story mode chains multiple captions so the music evolves across sections.
MusicLM matters as the research foundation behind Google's later Lyria music models, but this page is for listening to published examples, not creating new tracks interactively. Researchers and musicians study it for long-form consistency, painting-to-music conditioning, and melody transfer results documented in the 2023 paper.
FineShare FineVoice Upvotes
MusicLM Upvotes
FineShare FineVoice Top Features
1,500+ text-to-speech voices across 154 languages and accents
Voice cloning in 30 seconds with uploadable RVC models for custom workflows
AI voice changer with emotion tags like angry, happy, and sad for expressive speech
Speech-to-text exports in TXT, JSON, SRT, and VTT with automatic punctuation
Royalty-free AI sound effects and background music generated from text prompts
Developer API advertised with 99.9% uptime and JSON, SRT, and VTT output formats
MusicLM Top Features
Generates music at 24 kHz from rich text captions
Story mode chains multiple text prompts across timed segments
Text-and-melody conditioning transforms hummed or whistled tunes into new styles
Painting caption conditioning pairs artwork descriptions with generated audio
Long-generation examples cover melodic techno, swing, and relaxing jazz
MusicCaps dataset includes 5,500 expert-written music-text pairs
FineShare FineVoice Category
- Audio Generation
MusicLM Category
- Audio Generation
FineShare FineVoice Pricing Type
- Freemium
MusicLM Pricing Type
- Free