FineShare FineVoice vs VALL-E
In the clash of FineShare FineVoice vs VALL-E, which AI Audio Generation tool emerges victorious? We assess reviews, pricing, alternatives, features, upvotes, and more.
When we put FineShare FineVoice and VALL-E head to head, which one emerges as the victor?
Let's take a closer look at FineShare FineVoice and VALL-E, both of which are AI-driven audio generation tools, and see what sets them apart. In the race for upvotes, FineShare FineVoice takes the trophy. FineShare FineVoice has received 6 upvotes from aitools.fyi users, while VALL-E has received 5 upvotes.
Don't agree with the result? Cast your vote and be a part of the decision-making process!
FineShare FineVoice
What is FineShare FineVoice?
FineShare FineVoice is a browser-based AI audio studio for text-to-speech, voice changing, cloning, and sound design. You can generate narration from scripts, swap voices in recordings, design custom voices from text prompts, and create royalty-free sound effects or background music without opening separate apps.
Most voice generators focus on narration alone. FineVoice bundles speech-to-text, voice enhancement, lip sync, talking photos, and podcast generation in one workspace, plus a linked VoiceTrans desktop app with 1,000+ real-time voice models for games and chat. Video voiceover export and full video localization are still marked Coming Soon, so it fits audio-first creators more than teams that need finished video exports today.
YouTube creators, podcasters, educators, marketers, and developers use FineVoice for multilingual voiceovers, character acting, and API-driven apps. The marketing site advertises no sign-up for core online trials, with paid tiers that raise monthly character quotas, clone slots, and speech-to-text minutes.
VALL-E
What is VALL-E?
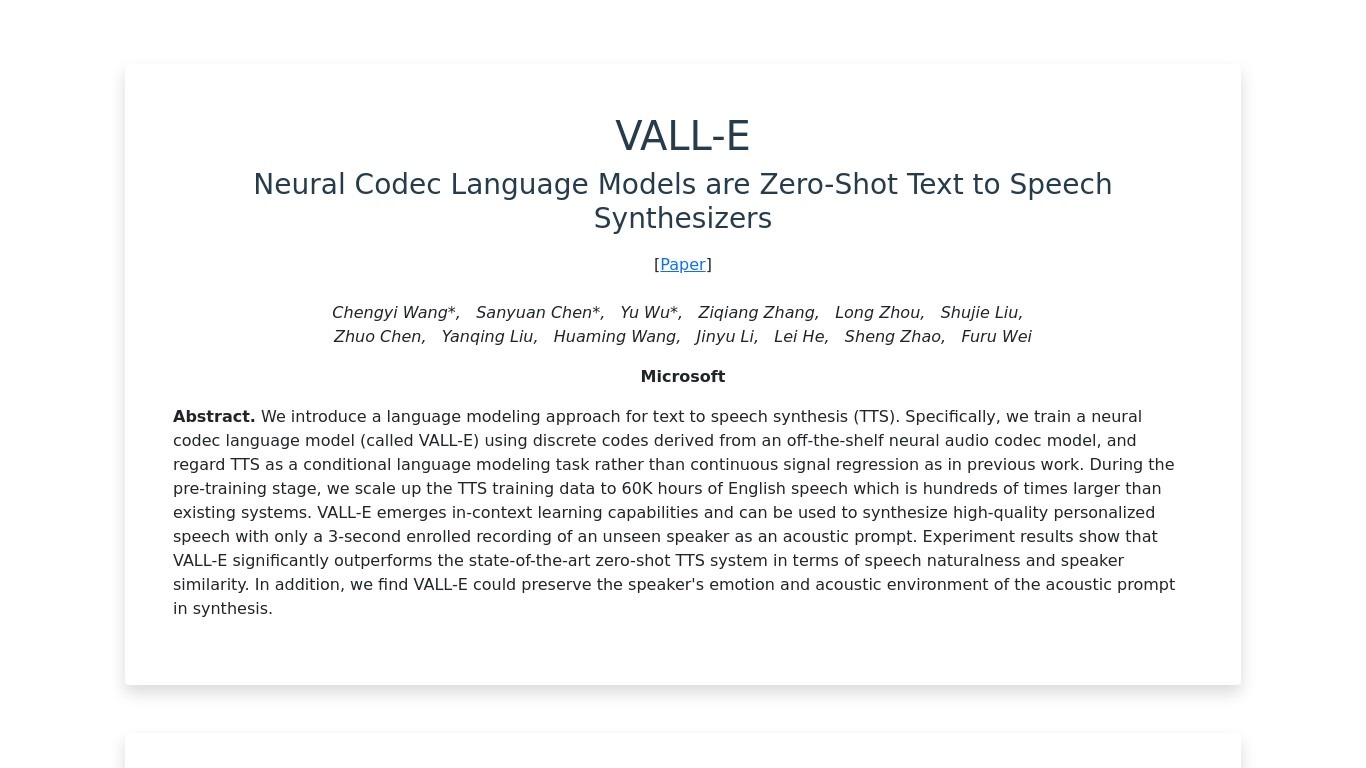
VALL-E is a Microsoft Research text-to-speech model that clones a speaker's voice from a short audio clip and generates new speech from text. It belongs to the audio generation category because it synthesizes natural speech rather than editing existing recordings. The project page hosts sample audio for the original VALL-E model and later variants in the same research family.
Most TTS systems regress continuous waveforms or mel-spectrograms directly. VALL-E instead treats speech as a conditional language modeling task over discrete codes from a neural audio codec. Microsoft trained it on about 60,000 hours of English speech, far larger than typical TTS datasets. A 3-second enrolled recording of an unseen speaker is enough to drive zero-shot synthesis, and the model can keep the emotion and room tone present in that prompt.
The VALL-E family grew beyond the first paper. VALL-E X handles cross-lingual zero-shot TTS, VALL-E R adds phoneme monotonic alignment for more stable speech generation, and VALL-E 2 pairs repetition-aware sampling with grouped code modeling to reach human parity on LibriSpeech and VCTK benchmarks. Related lines like MELLE, FELLE, and PALLE explore continuous mel tokens and hybrid autoregressive plus parallel decoding.
Researchers, speech engineers, and curious listeners use VALL-E to hear what large-scale codec language models can do before building their own pipelines. The public samples are research demos, not a hosted API you can plug into a product without separate licensing and ethics review.
FineShare FineVoice Upvotes
VALL-E Upvotes
FineShare FineVoice Top Features
1,500+ text-to-speech voices across 154 languages and accents
Voice cloning in 30 seconds with uploadable RVC models for custom workflows
AI voice changer with emotion tags like angry, happy, and sad for expressive speech
Speech-to-text exports in TXT, JSON, SRT, and VTT with automatic punctuation
Royalty-free AI sound effects and background music generated from text prompts
Developer API advertised with 99.9% uptime and JSON, SRT, and VTT output formats
VALL-E Top Features
Clones an unseen speaker from a 3-second enrolled audio prompt
Pre-trained on about 60,000 hours of English speech data
VALL-E 2 reports human parity on LibriSpeech and VCTK zero-shot benchmarks
Preserves speaker emotion and acoustic environment from the prompt clip
VALL-E X extends zero-shot synthesis to cross-lingual scenarios
Sample pages cover seven model lines including MELLE, FELLE, and PALLE
FineShare FineVoice Category
- Audio Generation
VALL-E Category
- Audio Generation
FineShare FineVoice Pricing Type
- Freemium
VALL-E Pricing Type
- Free