FinetuneFast vs Helicone
Explore the showdown between FinetuneFast vs Helicone and find out which AI Large Language Model (LLM) tool wins. We analyze upvotes, features, reviews, pricing, alternatives, and more.
When comparing FinetuneFast and Helicone, which one rises above the other?
When we contrast FinetuneFast with Helicone, both of which are exceptional AI-operated large language model (llm) tools, and place them side by side, we can spot several crucial similarities and divergences. In the race for upvotes, FinetuneFast takes the trophy. FinetuneFast has been upvoted 8 times by aitools.fyi users, and Helicone has been upvoted 6 times.
Want to flip the script? Upvote your favorite tool and change the game!
FinetuneFast
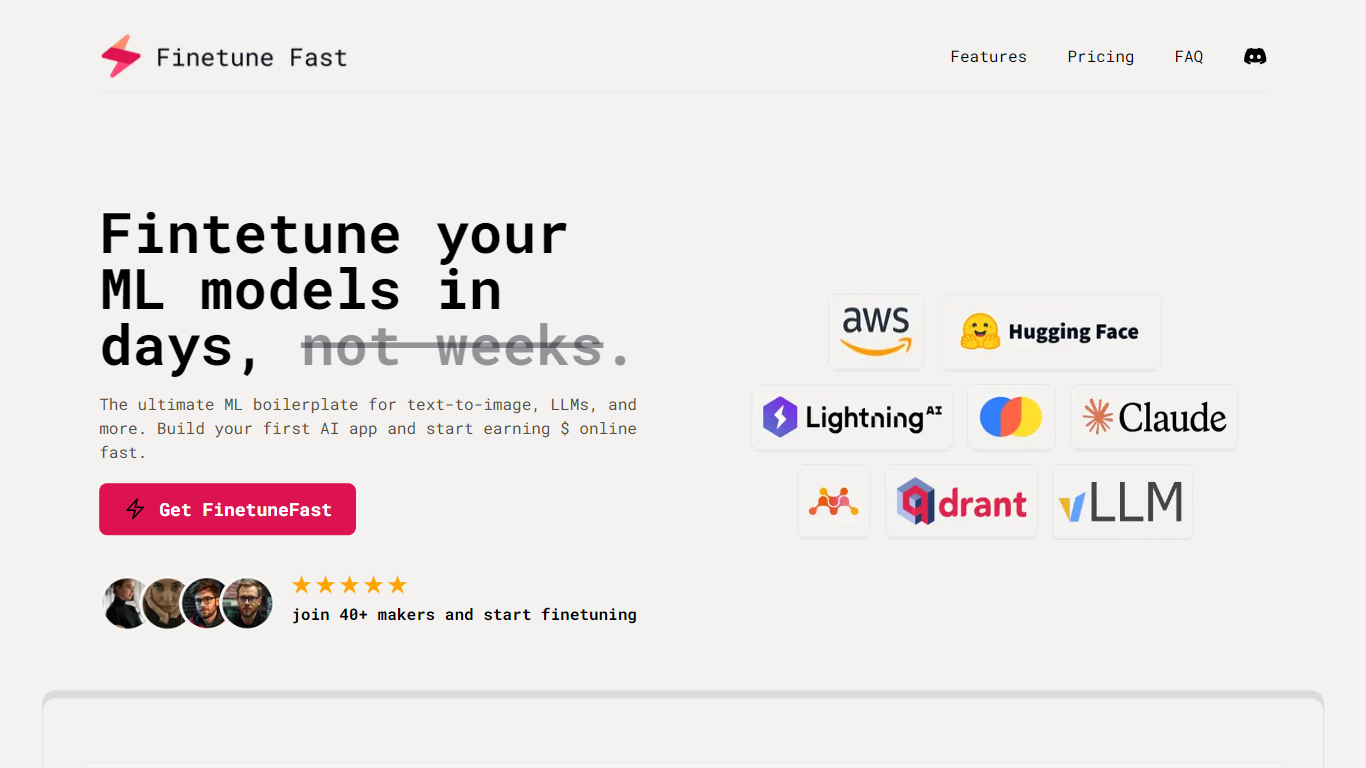

What is FinetuneFast?
FinetuneFast is a paid boilerplate kit for fine-tuning and deploying machine learning models. It bundles pre-configured training scripts, data loading pipelines, hyperparameter optimization, and deployment templates so developers can move from setup to production faster than building everything from scratch.
The package covers text-to-image, large language models, RAG applications, and related workflows. Included examples reference providers such as AWS Bedrock, Mistral AI, and OpenAI, along with templates for Flux-Schnell text-to-image, Fish-Speech text-to-speech, and retrieval-augmented generation.
After purchase, buyers receive access to GitHub repository materials with documentation. The All In plan adds Discord community access and lifetime updates. Founder Patrick built the product from hands-on ML engineering experience, including work on model training, inference APIs, and scalable infrastructure.
Helicone
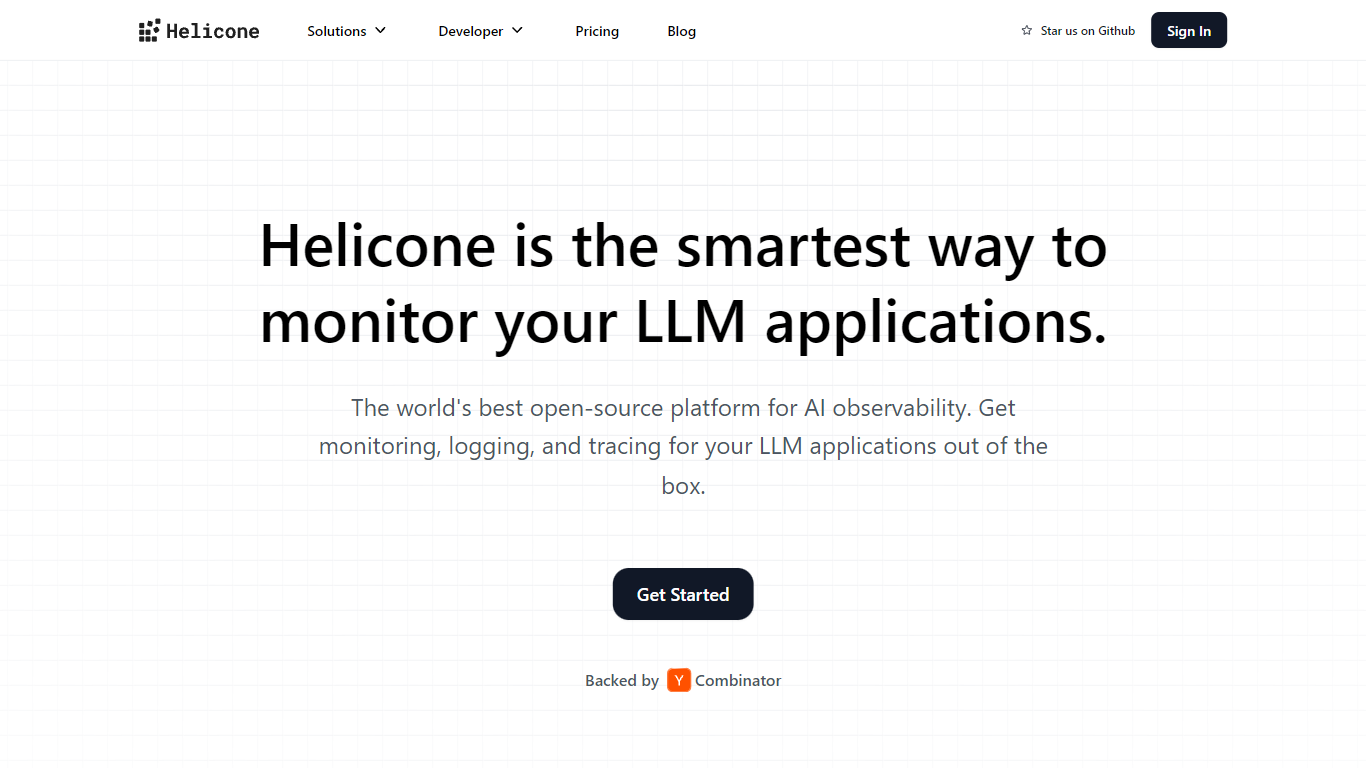
What is Helicone?
Helicone is an open-source AI gateway and observability platform for production LLM apps. Point the OpenAI SDK at https://ai-gateway.helicone.ai and you can call 100+ models from OpenAI, Anthropic, Google, and other providers while Helicone logs latency, token usage, cost, and errors automatically.
Most model routers charge a markup and bolt observability on later. Helicone combines routing with monitoring: automatic provider failover, cross-provider caching, granular rate limits, session tracking, and a unified dashboard for debugging prompts. The credits product advertises 0% markup on model usage, so you pay provider rates plus standard payment processing rather than a platform surcharge.
Helicone's Hobby plan includes 10,000 monitored requests per month with a 7-day retention window, while Pro and Team tiers add longer retention, higher ingestion limits, prompts, datasets, and gateway features like caching and automatic fallbacks. The company is open source with self-host and managed cloud options, and the homepage notes Helicone joined Mintlify in 2026.
FinetuneFast Upvotes
Helicone Upvotes
FinetuneFast Top Features
Pre-configured training scripts with multi-GPU support and no-code fine-tuning options
Efficient data loading pipelines for preparing and organizing training datasets
Hyperparameter optimization tools to tune model performance
One-click deployment with auto-scaling infrastructure and generated API endpoints
Production-ready inference boilerplates, RAG examples, and AI SaaS starter templates
Model coverage includes Flux-Schnell, Mistral, OpenAI integrations, Fish-Speech TTS, and RAG workflows
Helicone Top Features
OpenAI-compatible gateway endpoint at ai-gateway.helicone.ai for 100+ LLM providers
Automatic provider failover, load balancing, and intelligent cheapest-route selection
Built-in observability with sessions, user analytics, custom properties, and cost tracking
Hobby plan includes 10,000 requests per month with 7-day log retention
Cross-provider caching and granular rate limits by user, team, or cost
0% markup Helicone Credits billing across OpenAI, Anthropic, Google, and other providers
Open-source codebase with self-hosted and managed cloud deployment options
FinetuneFast Category
- Large Language Model (LLM)
Helicone Category
- Large Language Model (LLM)
FinetuneFast Pricing Type
- Paid
Helicone Pricing Type
- Freemium