LMNT vs MusicLM
When comparing LMNT vs MusicLM, which AI Audio Generation tool shines brighter? We look at pricing, alternatives, upvotes, features, reviews, and more.
In a comparison between LMNT and MusicLM, which one comes out on top?
When we put LMNT and MusicLM side by side, both being AI-powered audio generation tools, The upvote count is neck and neck for both LMNT and MusicLM. You can help us determine the winner by casting your vote and tipping the scales in favor of one of the tools.
Disagree with the result? Upvote your favorite tool and help it win!
LMNT

What is LMNT?
LMNT is an audio generation API for turning text into lifelike speech in live products. It targets conversational apps, voice agents, games, and other experiences where latency and voice quality both matter.
Most text-to-speech APIs cap voice clones or throttle concurrent streams. LMNT includes unlimited voice clones on every API plan, advertises no concurrency or rate limits, and streams audio in roughly 150 to 200 milliseconds. That trade-off favors builders shipping real-time voice rather than batch narration.
The product pairs a free web playground with a developer API. You can preview voices in the browser, then wire the same models into your app through streaming endpoints built for real-time use.
LMNT is built by a small team in Palo Alto with backgrounds at Google[x], Meta, Microsoft, and other startups. The company is backed by investors including Elad Gil and Conviction, and lists SOC-2 Type II compliance on its site. Customers shown on the homepage include Khan Academy, HeyGen, Vapi, Vercel, Unity, and Replit.
MusicLM
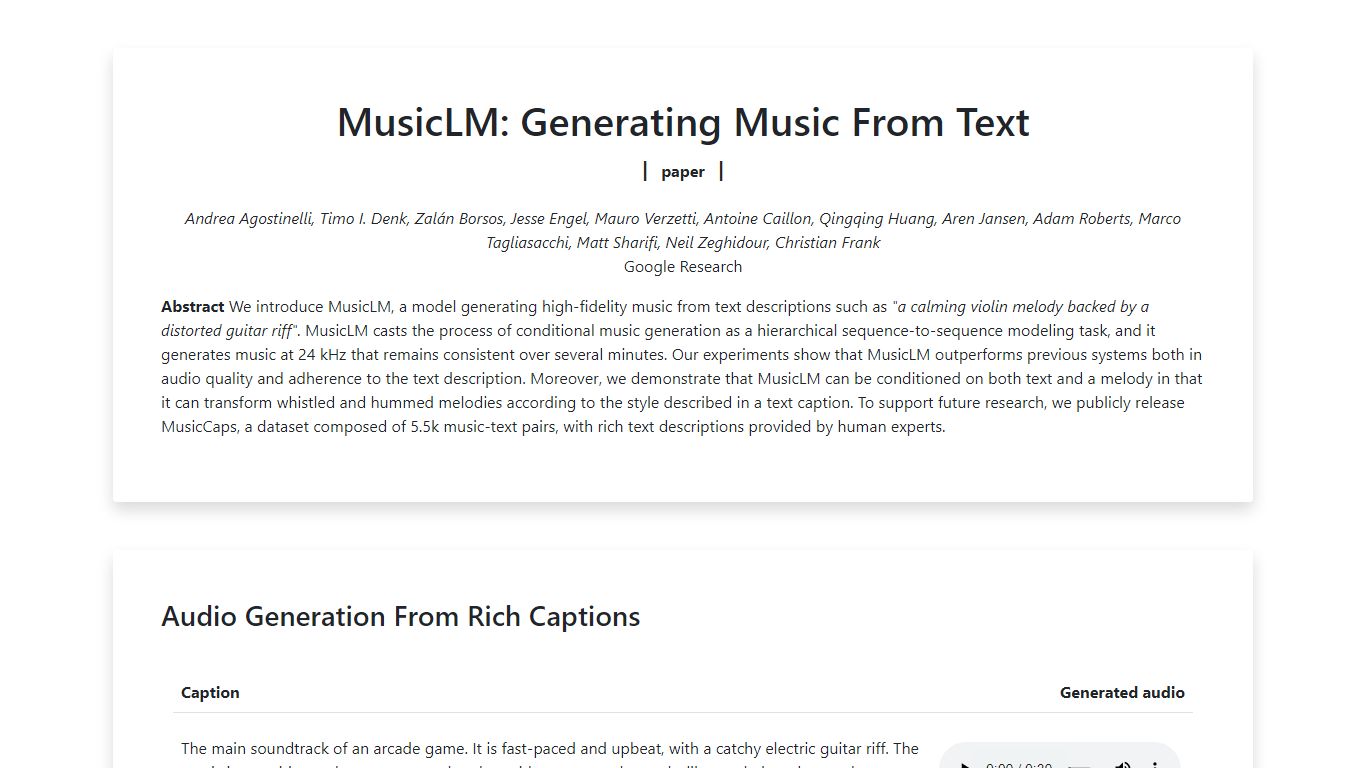
What is MusicLM?
MusicLM is a Google Research audio generation model that creates music from text captions at 24 kHz. The public examples page hosts sample clips for prompts like arcade soundtracks, reggaeton-EDM fusions, and relaxing jazz, plus longer story-mode generations that shift styles across timed segments. Google released the MusicCaps dataset of 5,500 music-text pairs alongside the paper.
Unlike consumer apps that ship one prompt box, MusicLM was published as a research demo with pre-generated samples rather than a login product. Its headline trick is joint text-and-melody conditioning: you can hum or whistle a tune and have the model re-render it in a new genre described in text. Story mode chains multiple captions so the music evolves across sections.
MusicLM matters as the research foundation behind Google's later Lyria music models, but this page is for listening to published examples, not creating new tracks interactively. Researchers and musicians study it for long-form consistency, painting-to-music conditioning, and melody transfer results documented in the 2023 paper.
LMNT Upvotes
MusicLM Upvotes
LMNT Top Features
Clone a studio-quality voice from a 5-second recording
Generate speech in 31 languages, including mid-sentence language switches
Stream audio with roughly 150-200ms latency for live conversations
Use unlimited voice clones on API plans with no concurrency caps
Try voices free in the web playground before integrating the API
MusicLM Top Features
Generates music at 24 kHz from rich text captions
Story mode chains multiple text prompts across timed segments
Text-and-melody conditioning transforms hummed or whistled tunes into new styles
Painting caption conditioning pairs artwork descriptions with generated audio
Long-generation examples cover melodic techno, swing, and relaxing jazz
MusicCaps dataset includes 5,500 expert-written music-text pairs
LMNT Category
- Audio Generation
MusicLM Category
- Audio Generation
LMNT Pricing Type
- Freemium
MusicLM Pricing Type
- Free