Moshi AI vs VALL-E
Explore the showdown between Moshi AI vs VALL-E and find out which AI Audio Generation tool wins. We analyze upvotes, features, reviews, pricing, alternatives, and more.
When comparing Moshi AI and VALL-E, which one rises above the other?
When we contrast Moshi AI with VALL-E, both of which are exceptional AI-operated audio generation tools, and place them side by side, we can spot several crucial similarities and divergences. With more upvotes, Moshi AI is the preferred choice. Moshi AI has been upvoted 6 times by aitools.fyi users, and VALL-E has been upvoted 5 times.
Disagree with the result? Upvote your favorite tool and help it win!
Moshi AI

What is Moshi AI?
Moshi AI is a speech-native conversational model from Kyutai, a Paris-based open-science research lab. Instead of chaining speech recognition, text generation, and text-to-speech, Moshi processes audio directly and holds full-duplex voice conversations with minimal latency.
Its multi-stream design runs separate channels for the user, Moshi's spoken output, and an Inner Monologue text stream that improves coherence. That setup lets Moshi listen and talk at the same time, handle overlaps, interruptions, and backchanneling like a real conversation rather than rigid speaker turns.
Moshi is built on Helium, a 7B language model, and Mimi, Kyutai's neural audio codec. Weights and inference code ship for PyTorch, Rust, and MLX, and you can try it in the browser at moshi-chat.kyutai.org. Researchers, voice AI developers, and anyone building real-time spoken interfaces will find the most value here.
VALL-E
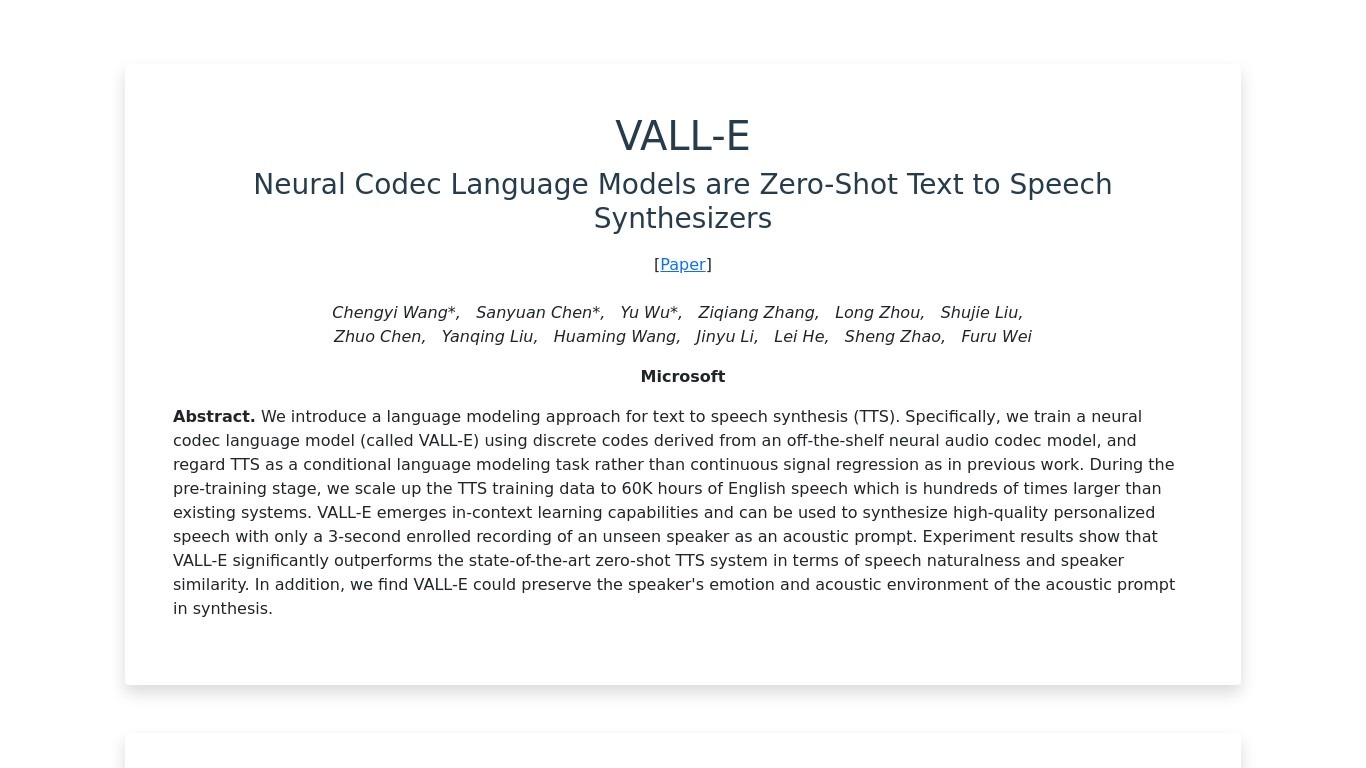
What is VALL-E?
VALL-E is a Microsoft Research text-to-speech model that clones a speaker's voice from a short audio clip and generates new speech from text. It belongs to the audio generation category because it synthesizes natural speech rather than editing existing recordings. The project page hosts sample audio for the original VALL-E model and later variants in the same research family.
Most TTS systems regress continuous waveforms or mel-spectrograms directly. VALL-E instead treats speech as a conditional language modeling task over discrete codes from a neural audio codec. Microsoft trained it on about 60,000 hours of English speech, far larger than typical TTS datasets. A 3-second enrolled recording of an unseen speaker is enough to drive zero-shot synthesis, and the model can keep the emotion and room tone present in that prompt.
The VALL-E family grew beyond the first paper. VALL-E X handles cross-lingual zero-shot TTS, VALL-E R adds phoneme monotonic alignment for more stable speech generation, and VALL-E 2 pairs repetition-aware sampling with grouped code modeling to reach human parity on LibriSpeech and VCTK benchmarks. Related lines like MELLE, FELLE, and PALLE explore continuous mel tokens and hybrid autoregressive plus parallel decoding.
Researchers, speech engineers, and curious listeners use VALL-E to hear what large-scale codec language models can do before building their own pipelines. The public samples are research demos, not a hosted API you can plug into a product without separate licensing and ethics review.
Moshi AI Upvotes
VALL-E Upvotes
Moshi AI Top Features
Processes speech directly without a text pipeline in the middle
Listens and talks simultaneously with overlap and interruption support
Inner Monologue text stream improves speech quality and reasoning
Runs real-time on an L4 GPU or M3 MacBook Pro via the Mimi codec
Open weights on Hugging Face with PyTorch, Rust, and MLX inference code
VALL-E Top Features
Clones an unseen speaker from a 3-second enrolled audio prompt
Pre-trained on about 60,000 hours of English speech data
VALL-E 2 reports human parity on LibriSpeech and VCTK zero-shot benchmarks
Preserves speaker emotion and acoustic environment from the prompt clip
VALL-E X extends zero-shot synthesis to cross-lingual scenarios
Sample pages cover seven model lines including MELLE, FELLE, and PALLE
Moshi AI Category
- Audio Generation
VALL-E Category
- Audio Generation
Moshi AI Pricing Type
- Free
VALL-E Pricing Type
- Free