Voiceful vs MusicLM
In the contest of Voiceful vs MusicLM, which AI Audio Generation tool is the champion? We evaluate pricing, alternatives, upvotes, features, reviews, and more.
If you had to choose between Voiceful and MusicLM, which one would you go for?
When we examine Voiceful and MusicLM, both of which are AI-enabled audio generation tools, what unique characteristics do we discover? The users have made their preference clear, Voiceful leads in upvotes. Voiceful has attracted 7 upvotes from aitools.fyi users, and MusicLM has attracted 6 upvotes.
Not your cup of tea? Upvote your preferred tool and stir things up!
Voiceful

What is Voiceful?
Voiceful lets game and media teams generate, morph, and process character voices inside their own apps. You can license a cross-platform C++ SDK, plug a Unity package into a game, or call a Cloud API when you want hosted processing instead of on-device synthesis.
Most consumer text-to-speech sites stop at a browser demo. Voiceful is built for integration: the Unity Characters plugin runs synthesis locally with no internet connection, and the wider toolkit covers real-time voice transformation (VoTrans), pitch correction (VoAlign), tempo and pitch shifting (VoScale), and a virtual DAW-style mixer (VoMix). That breadth matters when you need character voices, singing, or post-production fixes in the same pipeline.
Game studios, app developers, and media producers are the core buyers. Spotify, Soundtrap, Voicemod, and Yamaha Vocaloid appear on the client list, which signals use in music, social voice apps, and professional audio workflows rather than casual note dictation.
MusicLM
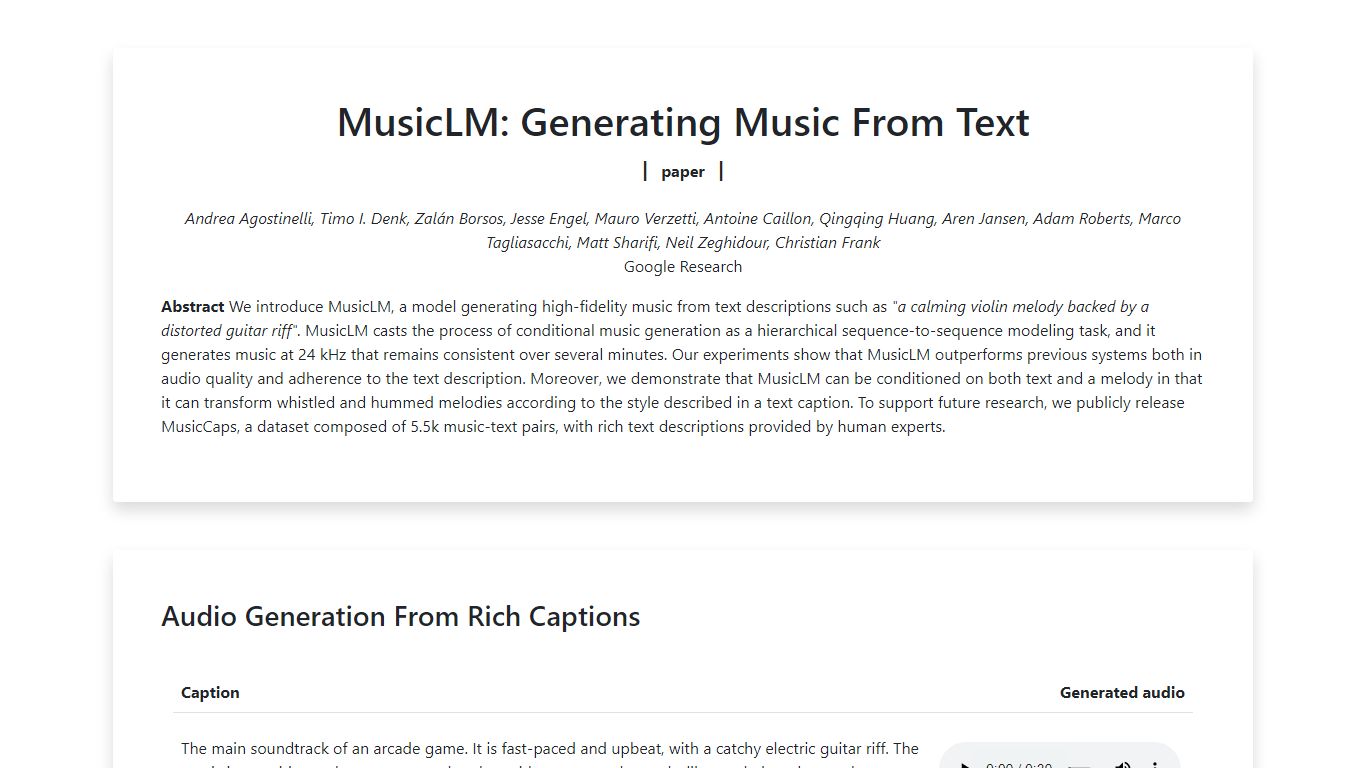
What is MusicLM?
MusicLM is a Google Research audio generation model that creates music from text captions at 24 kHz. The public examples page hosts sample clips for prompts like arcade soundtracks, reggaeton-EDM fusions, and relaxing jazz, plus longer story-mode generations that shift styles across timed segments. Google released the MusicCaps dataset of 5,500 music-text pairs alongside the paper.
Unlike consumer apps that ship one prompt box, MusicLM was published as a research demo with pre-generated samples rather than a login product. Its headline trick is joint text-and-melody conditioning: you can hum or whistle a tune and have the model re-render it in a new genre described in text. Story mode chains multiple captions so the music evolves across sections.
MusicLM matters as the research foundation behind Google's later Lyria music models, but this page is for listening to published examples, not creating new tracks interactively. Researchers and musicians study it for long-form consistency, painting-to-music conditioning, and melody transfer results documented in the 2023 paper.
Voiceful Upvotes
MusicLM Upvotes
Voiceful Top Features
Unity Characters ships Free, Lite (€60 EUR perpetual), and PRO tiers with 3, 10, or 10+ custom voice presets
Free Unity tier caps sentences at 5 words; Lite and PRO allow unlimited sentence length
Standalone C++ SDK targets iOS, Android, Desktop, and Server deployments with tier-based yearly licenses
Six named modules: VoSyn synthesis, VoTrans morphing, VoAlign alignment, VoDesc analysis, VoScale time/pitch, VoMix mixing
Cloud API REST endpoints hosted at cloud.voctrolabs.com with Python, PHP, and C++ sample code
Unity plugin synthesizes audio on-device with no internet connection or external dependencies
Client roster includes Spotify, Soundtrap, Voicemod, and Yamaha Vocaloid
MusicLM Top Features
Generates music at 24 kHz from rich text captions
Story mode chains multiple text prompts across timed segments
Text-and-melody conditioning transforms hummed or whistled tunes into new styles
Painting caption conditioning pairs artwork descriptions with generated audio
Long-generation examples cover melodic techno, swing, and relaxing jazz
MusicCaps dataset includes 5,500 expert-written music-text pairs
Voiceful Category
- Audio Generation
MusicLM Category
- Audio Generation
Voiceful Pricing Type
- Paid
MusicLM Pricing Type
- Free