AssemblyAI vs MusicLM
In the contest of AssemblyAI vs MusicLM, which AI Audio Generation tool is the champion? We evaluate pricing, alternatives, upvotes, features, reviews, and more.
If you had to choose between AssemblyAI and MusicLM, which one would you go for?
When we examine AssemblyAI and MusicLM, both of which are AI-enabled audio generation tools, what unique characteristics do we discover? The upvote count reveals a draw, with both tools earning the same number of upvotes. Every vote counts! Cast yours and contribute to the decision of the winner.
Feeling rebellious? Cast your vote and shake things up!
AssemblyAI
What is AssemblyAI?
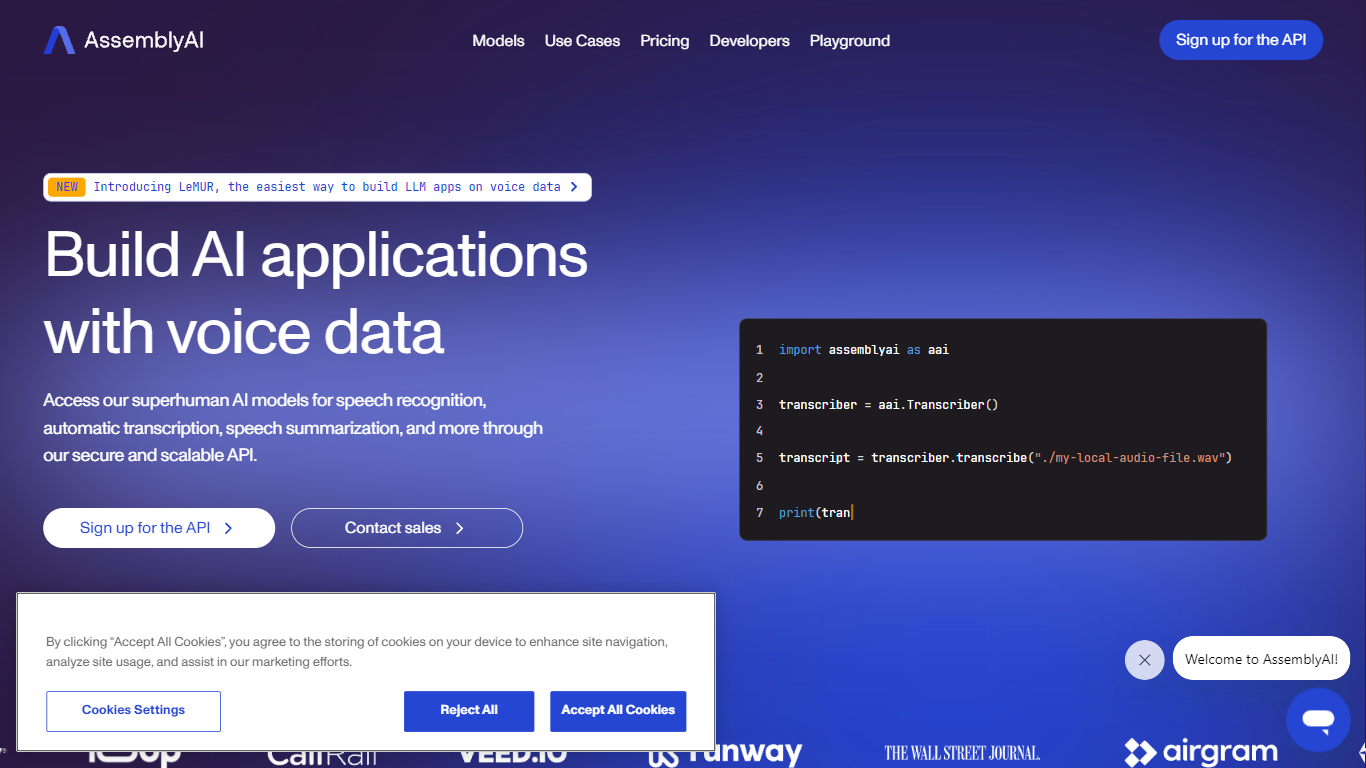
AssemblyAI gives developers APIs to transcribe, understand, and act on speech in production apps. The platform covers pre-recorded speech-to-text, real-time streaming transcription, a Voice Agent API over WebSocket, Speech Understanding add-ons, Guardrails, and an LLM Gateway for voice workflows. Teams wire it into call centers, voice agents, meeting tools, and media pipelines without hosting their own models.
General-purpose cloud speech APIs spread features across separate services. AssemblyAI stacks diarization, sentiment, entity detection, PII redaction, and topic tagging on the same transcription request with per-hour add-on pricing. That matters when you want speaker labels and moderation in one pass instead of chaining three vendors after the transcript lands.
Engineering teams building voice agents, compliance-heavy transcription, or multilingual products fit AssemblyAI best. Pricing is usage-based with $50 in free credits and no credit card required, but streaming bills per open WebSocket session rather than audio minutes alone. If you only need a simple one-off file transcript, a lighter consumer tool may be cheaper.
MusicLM
What is MusicLM?
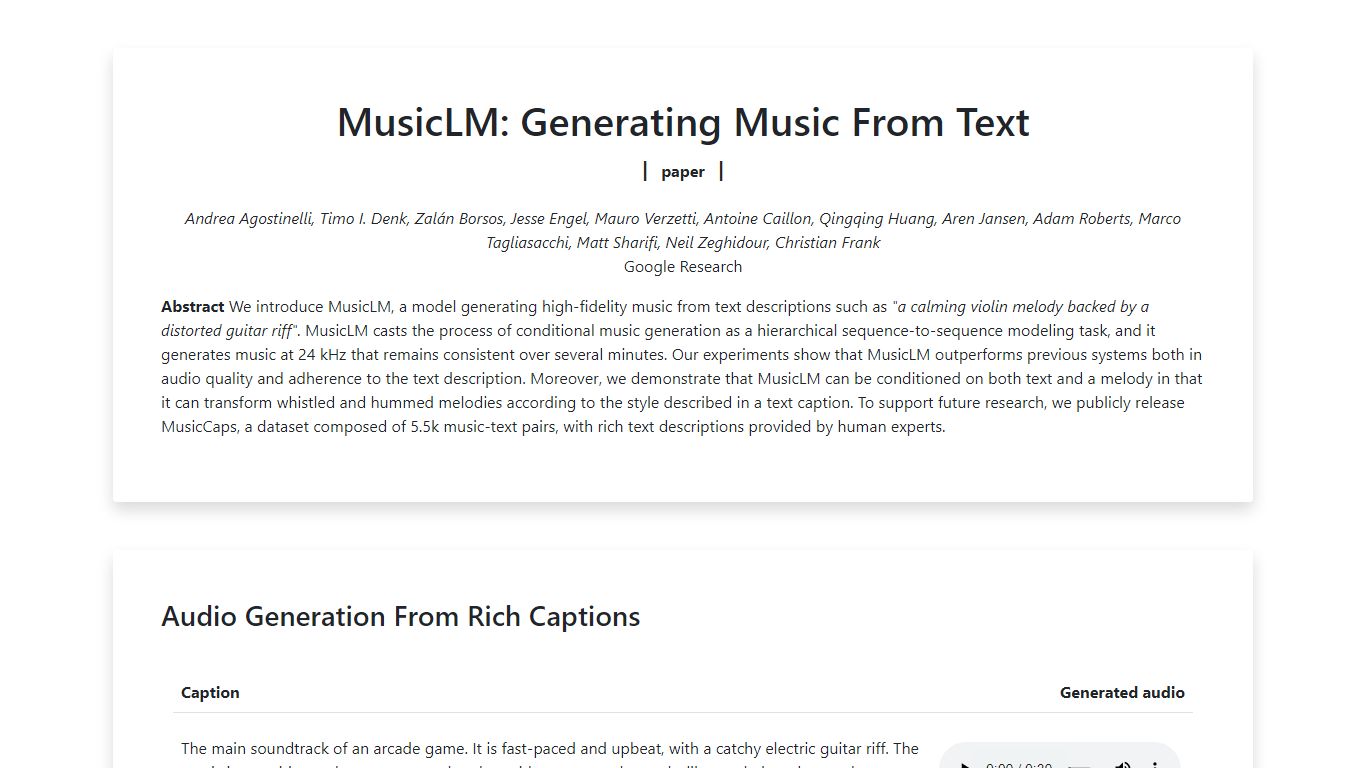
MusicLM is a Google Research audio generation model that creates music from text captions at 24 kHz. The public examples page hosts sample clips for prompts like arcade soundtracks, reggaeton-EDM fusions, and relaxing jazz, plus longer story-mode generations that shift styles across timed segments. Google released the MusicCaps dataset of 5,500 music-text pairs alongside the paper.
Unlike consumer apps that ship one prompt box, MusicLM was published as a research demo with pre-generated samples rather than a login product. Its headline trick is joint text-and-melody conditioning: you can hum or whistle a tune and have the model re-render it in a new genre described in text. Story mode chains multiple captions so the music evolves across sections.
MusicLM matters as the research foundation behind Google's later Lyria music models, but this page is for listening to published examples, not creating new tracks interactively. Researchers and musicians study it for long-form consistency, painting-to-music conditioning, and melody transfer results documented in the 2023 paper.
AssemblyAI Upvotes
MusicLM Upvotes
AssemblyAI Top Features
Universal-3.5 Pro async transcription is priced at $0.21 per hour of submitted audio
Real-time Universal-3.5 Pro streaming runs at $0.45 per hour of open WebSocket session time
Voice Agent API bills $4.50 per hour ($0.075 per minute) for speech-to-speech agents
Speech Understanding add-ons include diarization, sentiment, entity detection, and translation on one request
Platform reports 800M+ API calls processed monthly with coverage across 99 languages
MusicLM Top Features
Generates music at 24 kHz from rich text captions
Story mode chains multiple text prompts across timed segments
Text-and-melody conditioning transforms hummed or whistled tunes into new styles
Painting caption conditioning pairs artwork descriptions with generated audio
Long-generation examples cover melodic techno, swing, and relaxing jazz
MusicCaps dataset includes 5,500 expert-written music-text pairs
AssemblyAI Category
- Audio Generation
MusicLM Category
- Audio Generation
AssemblyAI Pricing Type
- Freemium
MusicLM Pricing Type
- Free