Cognee vs Falcon-40B on Hugging Face
Dive into the comparison of Cognee vs Falcon-40B on Hugging Face and discover which AI Large Language Model (LLM) tool stands out. We examine alternatives, upvotes, features, reviews, pricing, and beyond.
When comparing Cognee and Falcon-40B on Hugging Face, which one rises above the other?
When we compare Cognee and Falcon-40B on Hugging Face, two exceptional large language model (llm) tools powered by artificial intelligence, and place them side by side, several key similarities and differences come to light. The upvote count is neck and neck for both Cognee and Falcon-40B on Hugging Face. Your vote matters! Help us decide the winner among aitools.fyi users by casting your vote.
You don't agree with the result? Cast your vote to help us decide!
Cognee

What is Cognee?
Cognee turns documents, chats, tickets, and API data into graph memory language model agents can recall across sessions. It builds linked entity graphs from that context so agents stop restarting from scratch each run. You can connect Slack, GitHub, or Linear so coding agents and support bots share one permission-aware company brain.
Plain RAG returns similar text chunks. Cognee pairs vector search with knowledge graphs and auto-generated ontologies, so recall pulls connected entities and cited facts rather than isolated snippets. The SDK centers on four verbs, remember, recall, forget, and improve, and the same surface ships over HTTP and MCP for Claude Code, Codex, and OpenClaw.
Platform teams use it for coding agent memory, GraphRAG pipelines, deal intelligence, and customer-facing agents that need grounded answers. Run it with pip locally, self-host in Docker or on-prem, or move to Cognee Cloud when you want managed scale. The project reports 30.4k GitHub stars and 5M+ SDK runs per month, with production deployments at Bayer and Knowunity.
Falcon-40B on Hugging Face
What is Falcon-40B on Hugging Face?
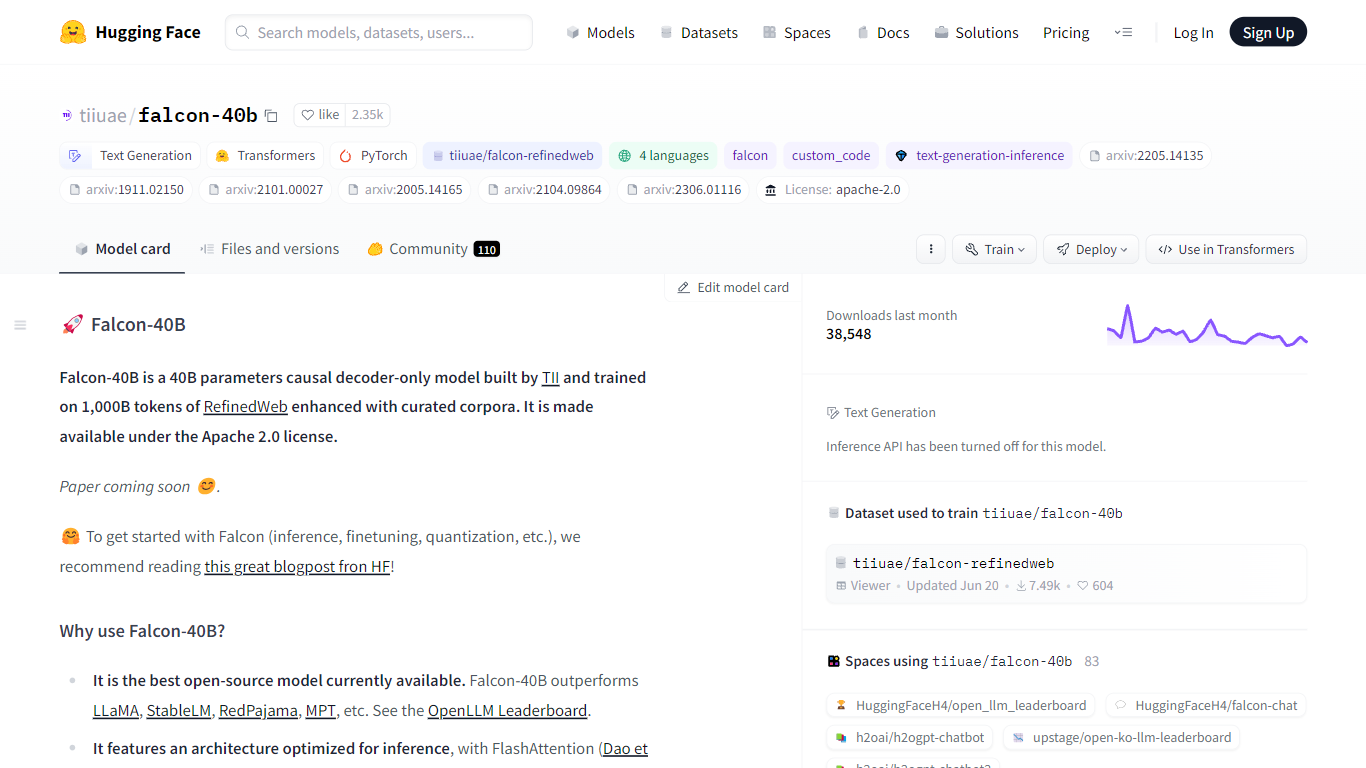
Falcon-40B on Hugging Face is a 40-billion-parameter causal decoder-only language model from the Technology Innovation Institute (TII), hosted as open weights on the Hugging Face Hub. You download the model and run it locally or on your own GPU cluster with Transformers, vLLM, SGLang, or quantized builds for Ollama and llama.cpp. It predicts the next token on a 2,048-token context window and ships as a raw pretrained checkpoint, not a chat-ready assistant.
Most open models at this size lean on heavily curated training mixes like The Pile. Falcon-40B was trained on 1,000 billion tokens drawn mostly from RefinedWeb, TII's filtered web crawl, with smaller slices of books, code, conversations, and technical papers. The architecture adds multiquery attention and FlashAttention on top of a GPT-3-style decoder, which TII tuned specifically for faster inference rather than chasing the widest possible task coverage out of the box.
Researchers and ML engineers reach for it as a finetuning base under the Apache 2.0 license, which allows commercial use without royalties. Running full-precision inference needs roughly 85 to 100 GB of GPU memory, so most production teams either quantize the weights or move to the smaller Falcon-7B sibling before deploying.
Cognee Upvotes
Falcon-40B on Hugging Face Upvotes
Cognee Top Features
pip install cognee connects Claude Code, Codex, or any MCP client in minutes
remember, recall, forget, and improve as the core API across SDK, HTTP, and MCP
30.4k GitHub stars and 5M+ SDK runs per month listed on the homepage
Hybrid graph and vector memory links entities across long conversations and sources
Free Cognee Cloud tier includes 1M tokens and one workspace at $0 per month
Ingest from Slack, Notion, Linear, Google Drive, S3, and code repos into one recall layer
BEAM 100K benchmark shows Cognee scoring 0.79 on the SDK results page
Falcon-40B on Hugging Face Top Features
40 billion parameters trained on 1,000B tokens, 75% from the RefinedWeb crawl
Apache 2.0 license permits commercial use and redistribution without royalties
60-layer architecture with multiquery attention, FlashAttention, and 2,048-token context
Load via Transformers, vLLM, SGLang, or Docker with trust_remote_code=True
Primary languages: English, German, Spanish, and French, plus limited support for 6 more European languages
Quantized builds available for Ollama, llama.cpp, LM Studio, and Jan local apps
Cognee Category
- Large Language Model (LLM)
Falcon-40B on Hugging Face Category
- Large Language Model (LLM)
Cognee Pricing Type
- Freemium
Falcon-40B on Hugging Face Pricing Type
- Free