
Last updated 07-30-2026
Category:
Reviews:
Join thousands of AI enthusiasts in the World of AI!
Falcon-40B on Hugging Face
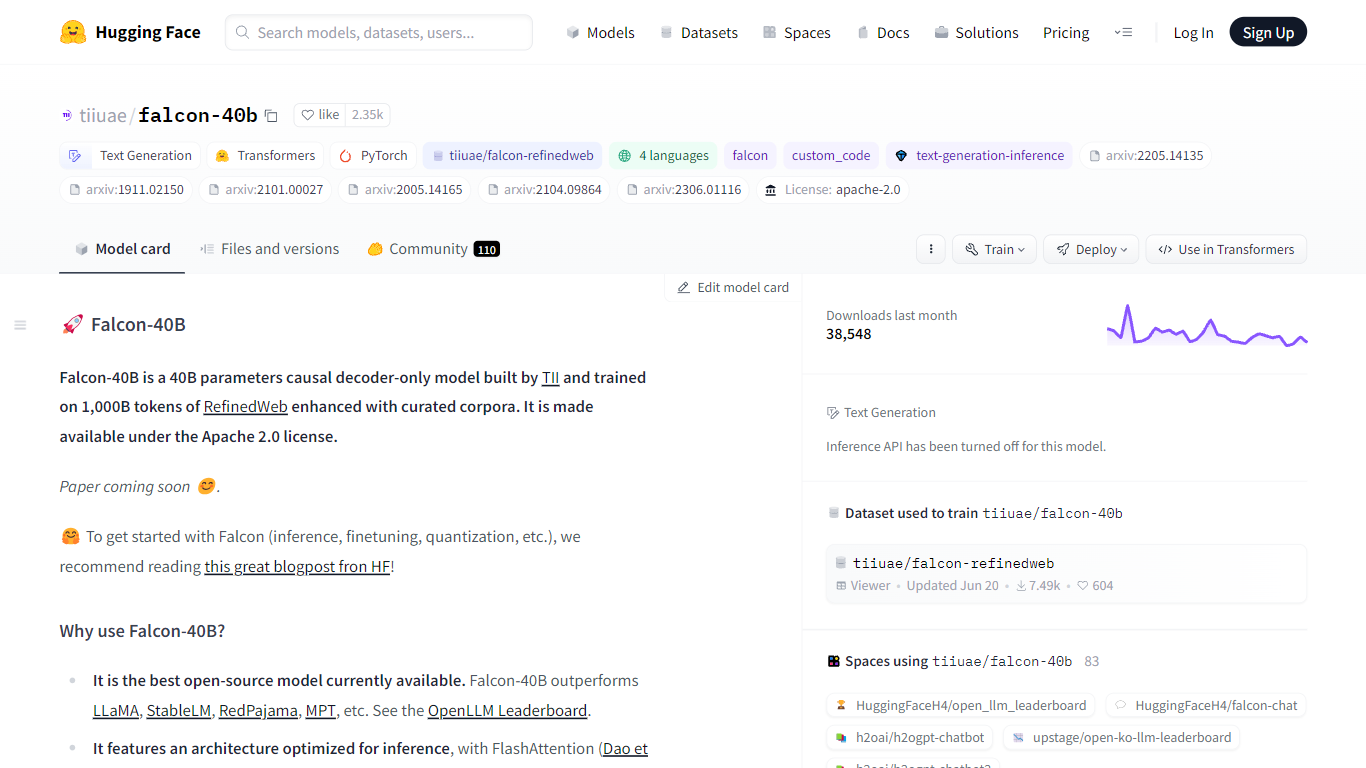
Falcon-40B on Hugging Face is a 40-billion-parameter causal decoder-only language model from the Technology Innovation Institute (TII), hosted as open weights on the Hugging Face Hub. You download the model and run it locally or on your own GPU cluster with Transformers, vLLM, SGLang, or quantized builds for Ollama and llama.cpp. It predicts the next token on a 2,048-token context window and ships as a raw pretrained checkpoint, not a chat-ready assistant.
Most open models at this size lean on heavily curated training mixes like The Pile. Falcon-40B was trained on 1,000 billion tokens drawn mostly from RefinedWeb, TII's filtered web crawl, with smaller slices of books, code, conversations, and technical papers. The architecture adds multiquery attention and FlashAttention on top of a GPT-3-style decoder, which TII tuned specifically for faster inference rather than chasing the widest possible task coverage out of the box.
Researchers and ML engineers reach for it as a finetuning base under the Apache 2.0 license, which allows commercial use without royalties. Running full-precision inference needs roughly 85 to 100 GB of GPU memory, so most production teams either quantize the weights or move to the smaller Falcon-7B sibling before deploying.
40 billion parameters trained on 1,000B tokens, 75% from the RefinedWeb crawl
Apache 2.0 license permits commercial use and redistribution without royalties
60-layer architecture with multiquery attention, FlashAttention, and 2,048-token context
Load via Transformers, vLLM, SGLang, or Docker with trust_remote_code=True
Primary languages: English, German, Spanish, and French, plus limited support for 6 more European languages
Quantized builds available for Ollama, llama.cpp, LM Studio, and Jan local apps
Apache 2.0 license allows commercial use without royalties or restrictions.
Multiquery attention and FlashAttention reduce inference memory and latency versus standard multi-head attention.
Trained on 1,000B tokens of RefinedWeb web data rather than a narrow curated corpus.
Runs through Transformers, vLLM, SGLang, and multiple quantized local app formats.
Full-precision inference needs 85 to 100 GB of GPU memory.
Ships as a raw pretrained base; most production tasks require finetuning or the Instruct variant.
No Hugging Face Inference Provider hosts this model, so there is no managed API endpoint.
Is Falcon-40B on Hugging Face free to download?
Yes. Falcon-40B on Hugging Face is released under the Apache 2.0 license with no download fee or usage royalty. You supply your own GPU hardware or cloud compute to run inference; Hugging Face does not charge for accessing the model weights.
How much GPU memory does Falcon-40B need?
Falcon-40B on Hugging Face requires at least 85 to 100 GB of memory for full-precision inference with Transformers. Quantized versions through Ollama or llama.cpp reduce that footprint, and the smaller Falcon-7B model needs far less hardware.
Can I use Falcon-40B commercially?
Yes. Falcon-40B on Hugging Face carries the Apache 2.0 license, which allows commercial use, modification, and distribution. TII still recommends finetuning and adding guardrails before deploying in production applications.
Is Falcon-40B ready for chat out of the box?
No. Falcon-40B on Hugging Face is a raw pretrained base model suited to research and finetuning. For instruction-following chat, TII points users to the separate Falcon-40B-Instruct checkpoint on Hugging Face.
What frameworks support Falcon-40B?
Falcon-40B on Hugging Face integrates with Hugging Face Transformers (requires PyTorch 2.0), vLLM, SGLang, and Docker Model Runner. Quantized variants work with Ollama, llama.cpp, LM Studio, and Jan through the model's quantization tree.
What languages does Falcon-40B support?
Falcon-40B on Hugging Face is trained primarily on English, German, Spanish, and French. It has limited capability in Italian, Portuguese, Polish, Dutch, Romanian, Czech, and Swedish, and will not generalize well to other languages.