FinetuneFast vs Falcon-40B on Hugging Face
In the clash of FinetuneFast vs Falcon-40B on Hugging Face, which AI Large Language Model (LLM) tool emerges victorious? We assess reviews, pricing, alternatives, features, upvotes, and more.
When we put FinetuneFast and Falcon-40B on Hugging Face head to head, which one emerges as the victor?
Let's take a closer look at FinetuneFast and Falcon-40B on Hugging Face, both of which are AI-driven large language model (llm) tools, and see what sets them apart. The upvote count favors FinetuneFast, making it the clear winner. FinetuneFast has received 8 upvotes from aitools.fyi users, while Falcon-40B on Hugging Face has received 6 upvotes.
Does the result make you go "hmm"? Cast your vote and turn that frown upside down!
FinetuneFast
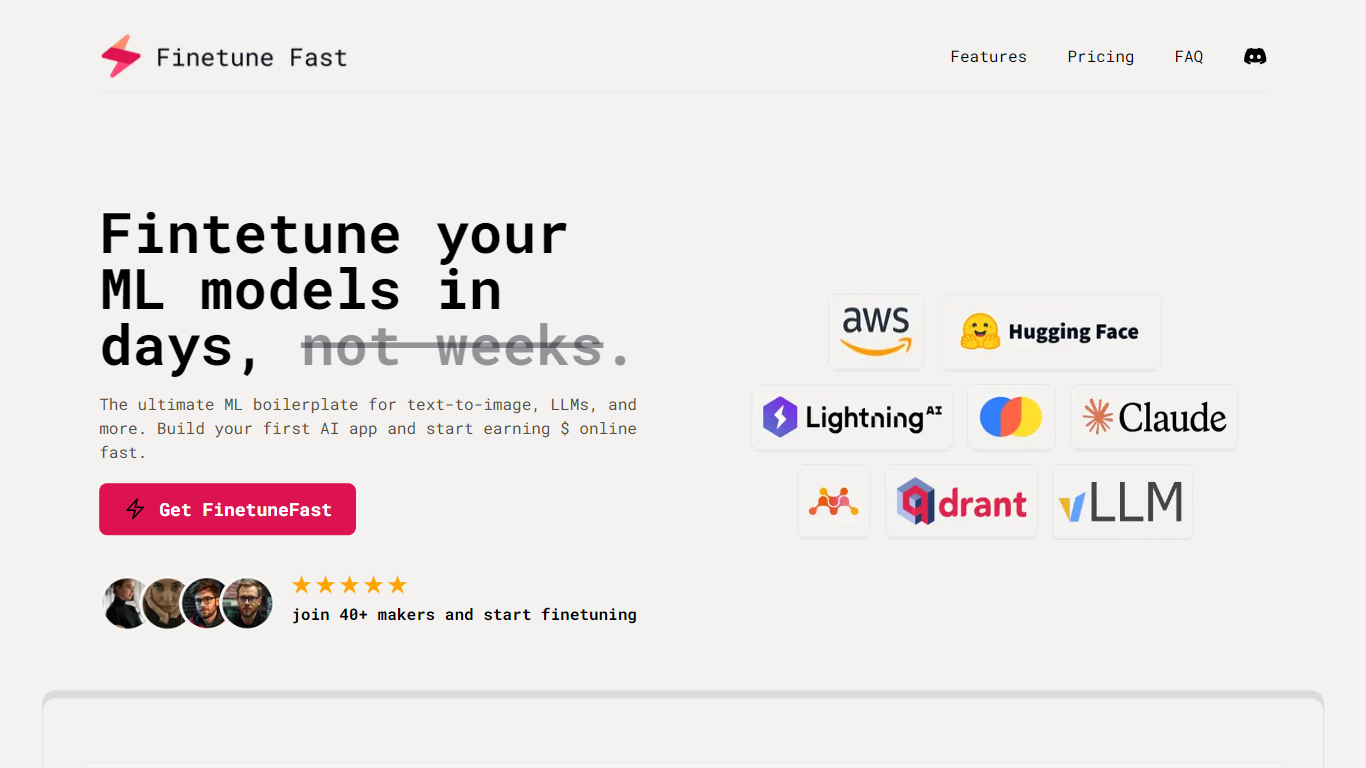

What is FinetuneFast?
FinetuneFast is a paid boilerplate kit for fine-tuning and deploying machine learning models. It bundles pre-configured training scripts, data loading pipelines, hyperparameter optimization, and deployment templates so developers can move from setup to production faster than building everything from scratch.
The package covers text-to-image, large language models, RAG applications, and related workflows. Included examples reference providers such as AWS Bedrock, Mistral AI, and OpenAI, along with templates for Flux-Schnell text-to-image, Fish-Speech text-to-speech, and retrieval-augmented generation.
After purchase, buyers receive access to GitHub repository materials with documentation. The All In plan adds Discord community access and lifetime updates. Founder Patrick built the product from hands-on ML engineering experience, including work on model training, inference APIs, and scalable infrastructure.
Falcon-40B on Hugging Face
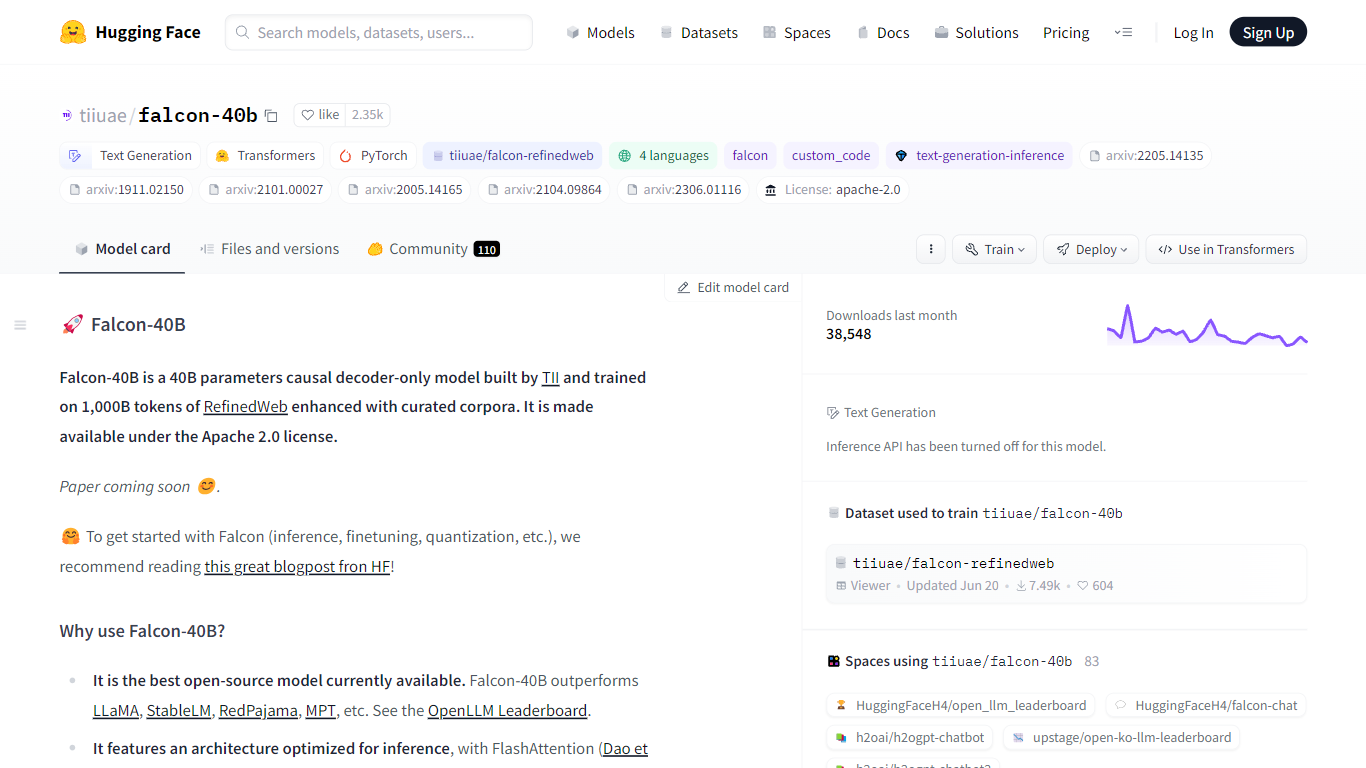
What is Falcon-40B on Hugging Face?
Falcon-40B on Hugging Face is a 40-billion-parameter causal decoder-only language model from the Technology Innovation Institute (TII), hosted as open weights on the Hugging Face Hub. You download the model and run it locally or on your own GPU cluster with Transformers, vLLM, SGLang, or quantized builds for Ollama and llama.cpp. It predicts the next token on a 2,048-token context window and ships as a raw pretrained checkpoint, not a chat-ready assistant.
Most open models at this size lean on heavily curated training mixes like The Pile. Falcon-40B was trained on 1,000 billion tokens drawn mostly from RefinedWeb, TII's filtered web crawl, with smaller slices of books, code, conversations, and technical papers. The architecture adds multiquery attention and FlashAttention on top of a GPT-3-style decoder, which TII tuned specifically for faster inference rather than chasing the widest possible task coverage out of the box.
Researchers and ML engineers reach for it as a finetuning base under the Apache 2.0 license, which allows commercial use without royalties. Running full-precision inference needs roughly 85 to 100 GB of GPU memory, so most production teams either quantize the weights or move to the smaller Falcon-7B sibling before deploying.
FinetuneFast Upvotes
Falcon-40B on Hugging Face Upvotes
FinetuneFast Top Features
Pre-configured training scripts with multi-GPU support and no-code fine-tuning options
Efficient data loading pipelines for preparing and organizing training datasets
Hyperparameter optimization tools to tune model performance
One-click deployment with auto-scaling infrastructure and generated API endpoints
Production-ready inference boilerplates, RAG examples, and AI SaaS starter templates
Model coverage includes Flux-Schnell, Mistral, OpenAI integrations, Fish-Speech TTS, and RAG workflows
Falcon-40B on Hugging Face Top Features
40 billion parameters trained on 1,000B tokens, 75% from the RefinedWeb crawl
Apache 2.0 license permits commercial use and redistribution without royalties
60-layer architecture with multiquery attention, FlashAttention, and 2,048-token context
Load via Transformers, vLLM, SGLang, or Docker with trust_remote_code=True
Primary languages: English, German, Spanish, and French, plus limited support for 6 more European languages
Quantized builds available for Ollama, llama.cpp, LM Studio, and Jan local apps
FinetuneFast Category
- Large Language Model (LLM)
Falcon-40B on Hugging Face Category
- Large Language Model (LLM)
FinetuneFast Pricing Type
- Paid
Falcon-40B on Hugging Face Pricing Type
- Free