GLM-130B vs LlamaIndex
Dive into the comparison of GLM-130B vs LlamaIndex and discover which AI Large Language Model (LLM) tool stands out. We examine alternatives, upvotes, features, reviews, pricing, and beyond.
When comparing GLM-130B and LlamaIndex, which one rises above the other?
When we compare GLM-130B and LlamaIndex, two exceptional large language model (llm) tools powered by artificial intelligence, and place them side by side, several key similarities and differences come to light. The upvote count shows a clear preference for GLM-130B. GLM-130B has garnered 7 upvotes, and LlamaIndex has garnered 6 upvotes.
You don't agree with the result? Cast your vote to help us decide!
GLM-130B
What is GLM-130B?
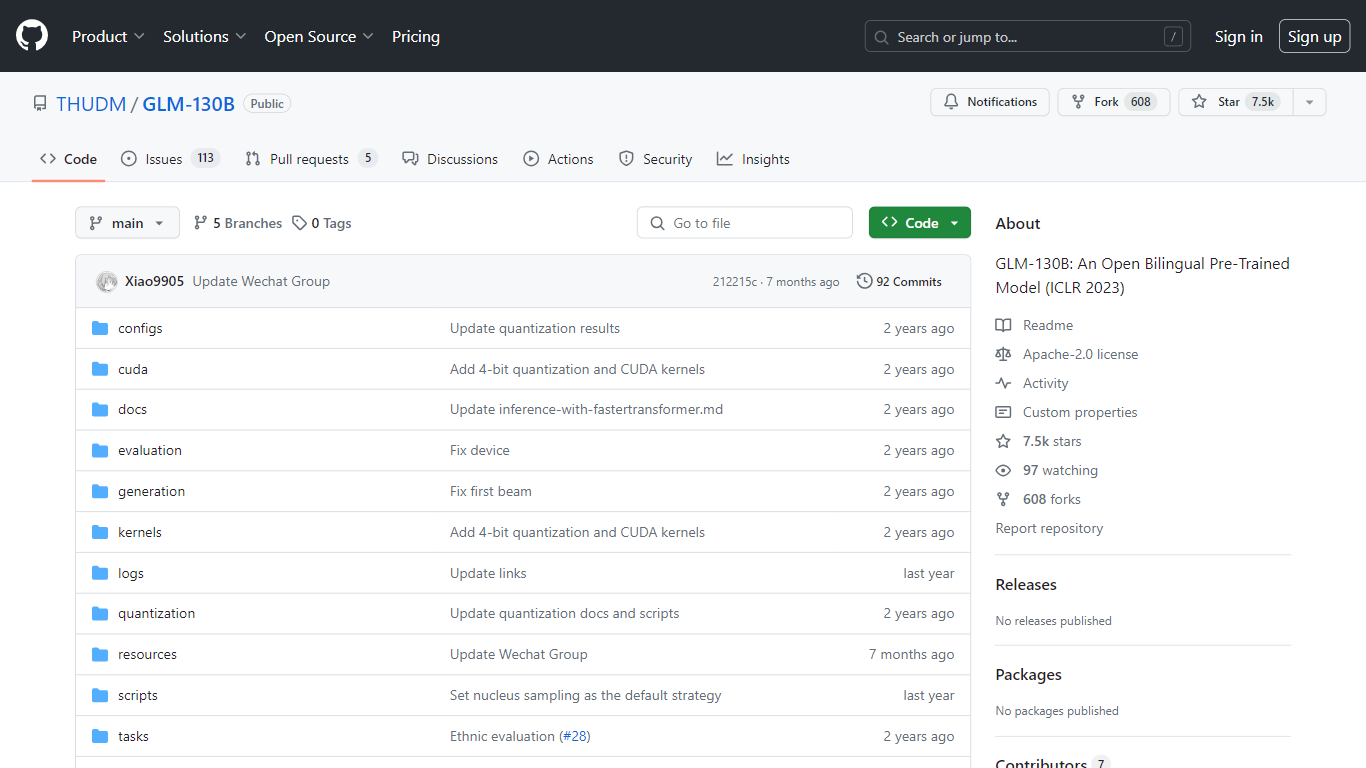
GLM-130B puts a 130-billion-parameter bilingual language model in the open research stack THUDM built around the General Language Model (GLM) pre-training recipe. The weights target English and Chinese text, and the GitHub repo ships inference code, evaluation tasks, and checkpoints accepted at ICLR 2023. You can run left-to-right generation or blank infilling with [MASK] and [gMASK] tokens on hardware that fits a single multi-GPU server rather than a proprietary API.
Where most 100B+ models stay behind closed doors, GLM-130B publishes model weights, training notes, and YAML configs for 30+ benchmarks. Its INT4 quantization path is tuned so four RTX 3090 (24GB) cards can host inference with almost no accuracy drop, a much lower bar than the eight A100 (40GB) setup used for full FP16 runs. The training objective mixes autoregressive blank infilling on 95% of tokens with multi-task instruction data from T0++ and DeepStruct, which is a different bet than standard causal GPT-style pre-training.
Researchers studying bilingual zero-shot transfer, large-model quantization, or reproducible LLM benchmarks will get the most from GLM-130B. The repo focuses on evaluation and inference tooling rather than a hosted chat product, though THUDM later spun dialogue work into ChatGLM. Expect to bring your own GPUs, storage for a 260GB checkpoint, and patience for the weight download form.
LlamaIndex
What is LlamaIndex?
Developers building LLM apps use LlamaIndex to parse messy documents before retrieval or agent steps. LlamaParse turns PDFs, scans, tables, charts, and handwritten notes into structured markdown and JSON, then adds schema-based extraction, classification, splitting, and indexing on top. Open-source LlamaIndex and Workflows libraries cover the same RAG building blocks for teams that want to self-host pieces of the stack.
Where generic OCR tools stop at plain text, LlamaParse routes pages through task-specific agents with auto-correction loops, so messy layouts survive as clean markdown or JSON without custom templates. Auto Mode picks a parse tier per page and can cut credit spend by up to 80%, which matters when you are processing invoices, claims, or technical manuals at volume rather than one-off uploads.
Teams in finance, insurance, manufacturing, and healthcare use LlamaIndex to feed LLMs and document agents with citation-backed fields instead of brittle copy-paste. Developers get Python and TypeScript SDKs, a REST API, and optional VPC deployment when SaaS data residency is not enough.
GLM-130B Upvotes
LlamaIndex Upvotes
GLM-130B Top Features
130 billion parameters trained on 400+ billion tokens split evenly between English and Chinese
Full FP16 inference on one server with 8 A100 (40GB) or 8 V100 (32GB) GPUs; INT4 quantization drops requirements to 4 RTX 3090 (24GB) cards
NVIDIA FasterTransformer integration reaches up to 2.5x faster decode than Megatron on A100 hardware
Repository ships YAML evaluation configs for 30+ NLP tasks with reproducible benchmark scripts
Two mask tokens support workflows: [MASK] for short blank filling and [gMASK] for left-to-right long generation
Model checkpoint ships as a 260GB archive split across 60 downloadable chunks after form-based access approval
LlamaIndex Top Features
Free tier includes 10,000 credits per month, roughly 1,000 pages at basic parse rates
Parses 130+ file types including PDF, Office docs, spreadsheets, and images
Agentic parse tiers with Auto Mode routing that can save up to 80% on credits
LlamaExtract returns field-level confidence scores and citations tied to source pages
Enterprise plans support VPC deployment with SOC 2, HIPAA, and GDPR compliance
Open-source LiteParse runs locally with no cloud tokens for PDF and Office parsing
Concurrent parse jobs scale from 5 on Free to 100 on Enterprise plans
GLM-130B Category
- Large Language Model (LLM)
LlamaIndex Category
- Large Language Model (LLM)
GLM-130B Pricing Type
- Free
LlamaIndex Pricing Type
- Freemium