MusicTGA-HR vs SpeechEasy
Dive into the comparison of MusicTGA-HR vs SpeechEasy and discover which AI Audio Generation tool stands out. We examine alternatives, upvotes, features, reviews, pricing, and beyond.
When comparing MusicTGA-HR and SpeechEasy, which one rises above the other?
When we compare MusicTGA-HR and SpeechEasy, two exceptional audio generation tools powered by artificial intelligence, and place them side by side, several key similarities and differences come to light. The upvote count is neck and neck for both MusicTGA-HR and SpeechEasy. Be a part of the decision-making process. Your vote could determine the winner.
Does the result make you go "hmm"? Cast your vote and turn that frown upside down!
MusicTGA-HR
What is MusicTGA-HR?
MusicTGA-HR is Amadeus Code's audio infrastructure API for teams building music AI products. It ships rights-cleared datasets with full mixes, six stem groups, multitrack audio, multitrack MIDI, and human-annotated metadata at 24-bit/48 kHz WAV quality. Developers query the catalog through REST endpoints or MCP with NeuroSync semantic search by mood, genre, BPM, or instruments.
Most public music datasets are noisy, rights-unclear, or missing stems and MIDI in one package. MusicTGA-HR targets that gap with a human-in-the-loop pipeline: semantic analysis, music-theory scoring, and musician review before tracks enter the API. Roland is listed as a trusted partner on the product page.
Generative AI labs, source-separation researchers, and BGM streaming products use it for training data, PoC trials, and production retrieval. Access is sales-led through dataset packages or API integration rather than a self-serve consumer app.
SpeechEasy
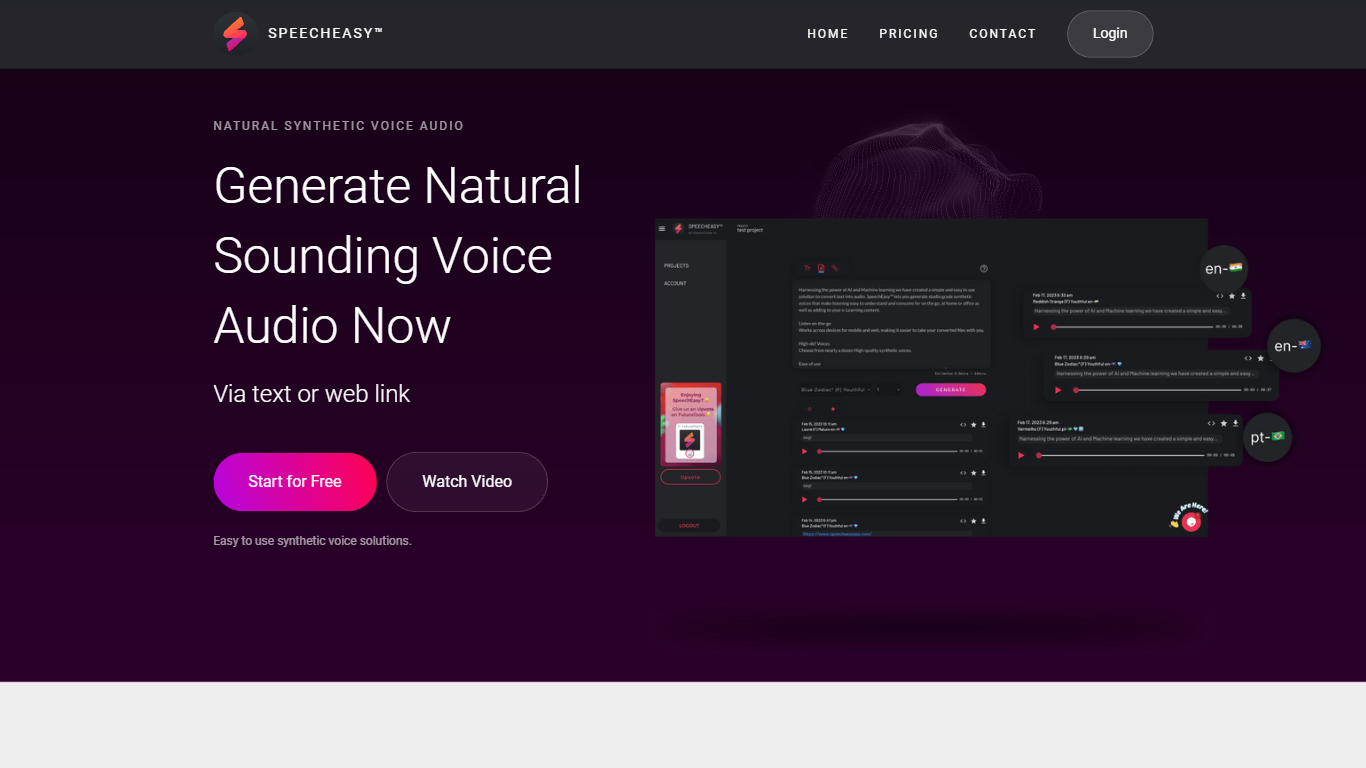
What is SpeechEasy?
SpeechEasy turns written text or a pasted web link into studio-grade synthetic voice audio you can play on desktop or mobile. The marketing site pitches it for listening on the go, at home, or in the office, and for dropping narration into e-learning content without recording a human voice.
Where heavier voice editors pack timelines, SSML, and cloning workflows, SpeechEasy keeps the surface area small: pick a voice, feed it text or a URL, and export audio. The free Starter tier still unlocks the full voice library, which is unusual in a category that often gates premium voices behind paid plans. Paid upgrades route through an in-app Content Creator purchase, while a Marketer tier remains listed as coming soon.
Course builders, marketers on tight video deadlines, and publishers turning articles into listenable files are the clearest fits. The homepage also calls out audiobook-style publishing and stakeholder-ready marketing voiceovers as named use cases.
MusicTGA-HR Upvotes
SpeechEasy Upvotes
MusicTGA-HR Top Features
10,000+ human-designed music classification categories with expert mood and energy tags
24-bit/48 kHz WAV full mixes plus six stem groups and multitrack MIDI per track
NeuroSync semantic search maps text queries to mood, instrumentation, and tempo matches
REST API and free MCP token for Claude, Cursor, and other MCP clients
Rights-cleared catalog cleared for commercial training, product integration, and research
Human-in-the-loop QA from musicians before audio enters the dataset
SpeechEasy Top Features
Accepts plain text or a web link as input and returns downloadable voice audio
Nearly a dozen high-definition synthetic voices, with more added regularly per the homepage
Starter plan is $0 and includes access to all voices plus core app features
Sign in and generate audio through beta1-app.speecheasyapp.com on desktop or mobile
Homepage pricing table lists 4 tiers: Starter, Content Creator, Marketer, and Enterprise
Privacy-first positioning with minimal personal data collection stated on the homepage
MusicTGA-HR Category
- Audio Generation
SpeechEasy Category
- Audio Generation
MusicTGA-HR Pricing Type
- Paid
SpeechEasy Pricing Type
- Freemium