OneOver vs BIG-bench
When comparing OneOver vs BIG-bench, which AI Large Language Model (LLM) tool shines brighter? We look at pricing, alternatives, upvotes, features, reviews, and more.
Between OneOver and BIG-bench, which one is superior?
When we put OneOver and BIG-bench side by side, both being AI-powered large language model (llm) tools, Neither tool takes the lead, as they both have the same upvote count. Be a part of the decision-making process. Your vote could determine the winner.
Want to flip the script? Upvote your favorite tool and change the game!
OneOver

What is OneOver?
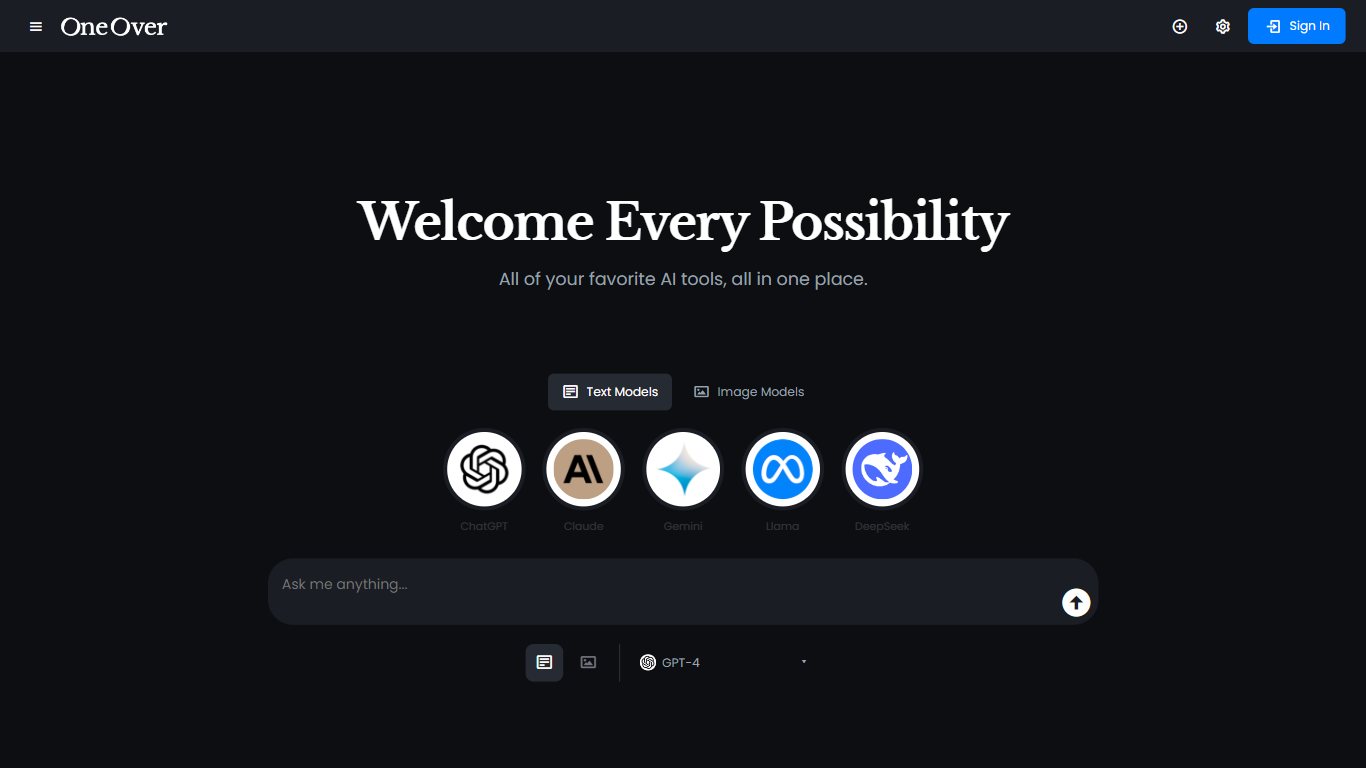
OneOver is a creative studio that puts multi-model chat, image generation, video, voice, and music in one browser workspace. You can run GPT, Claude, Gemini, Grok, and dozens of other models in a single thread, attach PDFs and images, flip on web search, and swap models without losing context. Guests get five chat messages before signup, and new accounts receive 50 one-time starter credits.
Where most tools make you pick one provider and buy separate subscriptions for images or video, OneOver routes everything through one shared credit balance. Subscription refills, plan bonuses, and pay-as-you-go packs all spend across chat, diffusion, video, speech, music, and playground mini apps. Switching from GPT-5.4 Nano to Claude Opus 5 is a dropdown change in the same conversation, not a copy-paste hop between sites.
Creators and marketers use OneOver to draft copy, iterate visuals, and turn prompts or photos into short clips from one library. Developers can hit the same model routes through a REST API with streaming support. Pro and Studio also ship seat-based team plans that pool monthly credits with member soft limits and one invoice.
BIG-bench
What is BIG-bench?
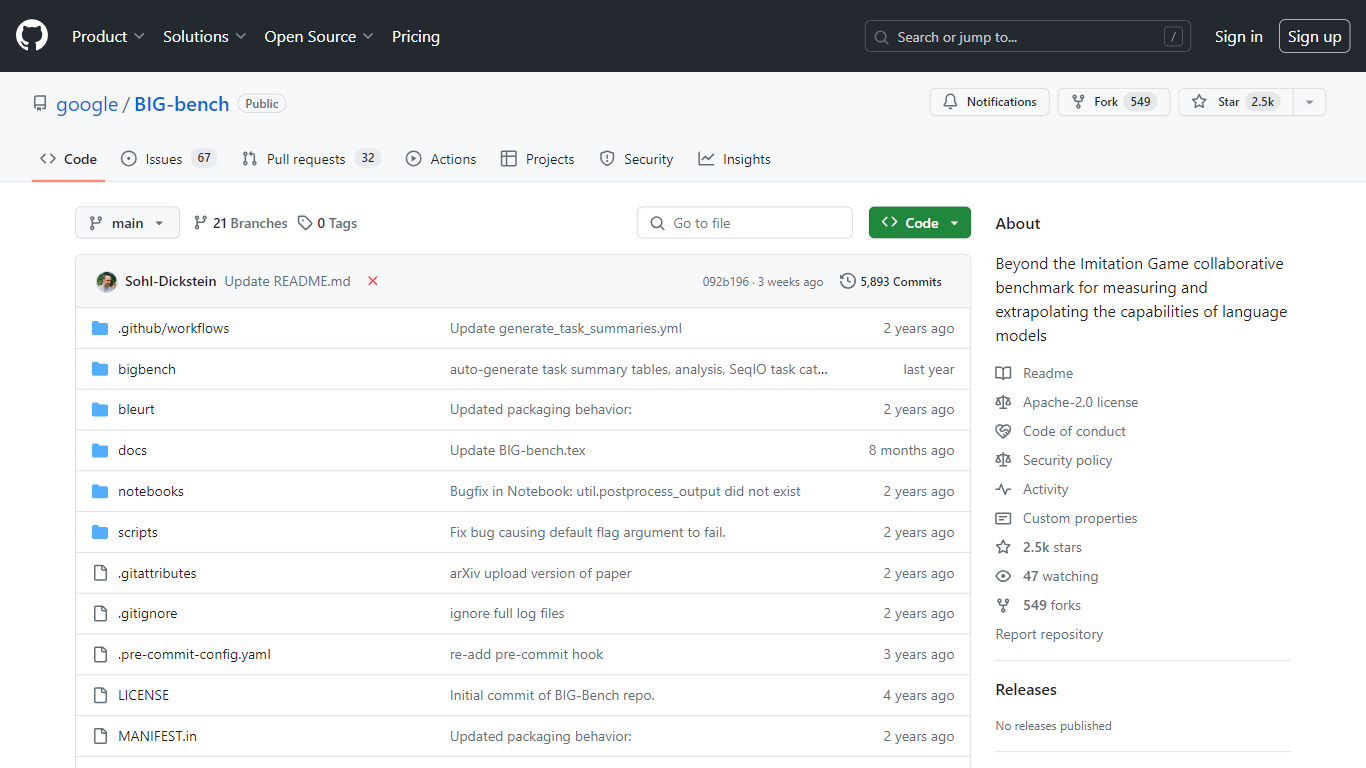
BIG-bench measures how well large language models handle reasoning, math, bias, and multilingual tasks across more than 200 community-written evaluation challenges. Google hosts the open source repository on GitHub, where researchers contributed tasks through pull requests and published comparative model scores on the leaderboard. Each task scores models through text generation or log-probability queries, using metrics like BLEU, BLEURT, and exact string match.
Unlike fixed benchmarks such as GLUE or SuperGLUE, BIG-bench grew through community pull requests, so task authors could submit challenges designed to exceed what existing models could solve. The suite also ships BIG-bench Lite, a 24-task subset that gives a cheaper canonical score across the full collection of 200+ tasks. Programmatic tasks support multi-turn model interaction, while JSON tasks work through a simpler task.json format with built-in scoring rules.
ML researchers use BIG-bench to compare model scaling trends and publish leaderboard results. Model developers run evaluations locally with HuggingFace models or through Docker scripts, then submit score files via pull request. The benchmark is archived and read-only as of April 2026, but the tasks, code, and published TMLR 2023 analysis paper remain available for reproducible research.
OneOver Upvotes
BIG-bench Upvotes
OneOver Top Features
Switch between GPT-5.6 Sol, Claude Opus 5, Gemini 3.6 Flash, and Grok 4.6 in one thread without losing context
Pro includes 1,400 credits per month (1,000 base plus 400 bonus) for chat, images, and short video work
Text-to-speech and text-to-music generators sit beside image and video studios in the same credit pool
Pay-as-you-go packs start at $5 for 500 credits that never expire and stack with subscription balances
REST API covers chat, image generation, and usage metering with streaming and one-field model swaps
Ten playground mini apps include Meme Generator, Upscaler, and Homework Helper with costs from 1 credit
BIG-bench Top Features
More than 200 benchmark tasks across JSON and programmatic formats, contributed via open pull requests
BIG-bench Lite packs 24 diverse tasks for a cheaper canonical model comparison score
Built-in metrics include BLEU, BLEURT, ROUGE, exact string match, and multiple-choice grading
SeqIO integration loads JSON tasks with 0-shot through 3-shot evaluation presets
Python 3.5 through 3.8 required; install with pip install -e . from the GitHub repository
OneOver Category
- Large Language Model (LLM)
BIG-bench Category
- Large Language Model (LLM)
OneOver Pricing Type
- Freemium
BIG-bench Pricing Type
- Free