SpeechEasy vs CassetteAi
In the face-off between SpeechEasy vs CassetteAi, which AI Audio Generation tool takes the crown? We scrutinize features, alternatives, upvotes, reviews, pricing, and more.
In a face-off between SpeechEasy and CassetteAi, which one takes the crown?
If we were to analyze SpeechEasy and CassetteAi, both of which are AI-powered audio generation tools, what would we find? The community has spoken, CassetteAi leads with more upvotes. CassetteAi has garnered 8 upvotes, and SpeechEasy has garnered 6 upvotes.
Disagree with the result? Upvote your favorite tool and help it win!
SpeechEasy

What is SpeechEasy?
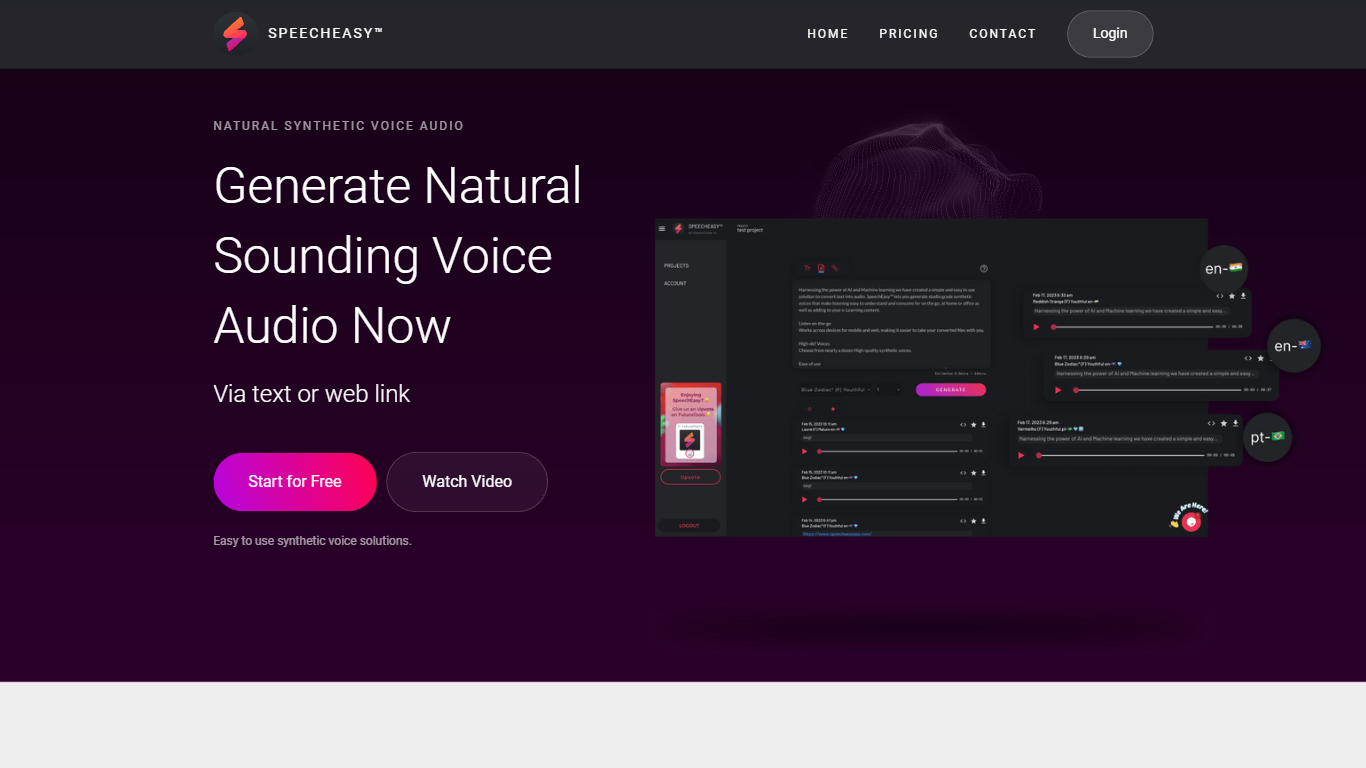
SpeechEasy turns written text or a pasted web link into studio-grade synthetic voice audio you can play on desktop or mobile. The marketing site pitches it for listening on the go, at home, or in the office, and for dropping narration into e-learning content without recording a human voice.
Where heavier voice editors pack timelines, SSML, and cloning workflows, SpeechEasy keeps the surface area small: pick a voice, feed it text or a URL, and export audio. The free Starter tier still unlocks the full voice library, which is unusual in a category that often gates premium voices behind paid plans. Paid upgrades route through an in-app Content Creator purchase, while a Marketer tier remains listed as coming soon.
Course builders, marketers on tight video deadlines, and publishers turning articles into listenable files are the clearest fits. The homepage also calls out audiobook-style publishing and stakeholder-ready marketing voiceovers as named use cases.
CassetteAi
What is CassetteAi?
CassetteAi is a real-time audio generation API for developers who need music, sound effects, or speech inside apps and games. Its models render a 30-second music sample in under 2 seconds and a full 3-minute track in under 10, at 44.1 kHz stereo. One SDK covers all three modalities through the same call shape.
Cloud audio APIs usually add round-trip latency that breaks interactive experiences. CassetteAi targets on-device inference with sub-50 millisecond time-to-first-audio and pay-per-second billing instead of monthly seats. The homepage cites 23 ms first-sample latency and deterministic seeds so game loops can re-roll SFX per frame without drift.
Music costs $0.02 per output minute and SFX costs $0.01 per generation, with no tier commitments. You call the models through fal.ai using JavaScript, Python, or cURL. Text-to-speech with zero-shot voice cloning is listed as launching soon.
Game studios, creator tools, and real-time media pipelines are the stated audience. Pixl Technologies runs the company from Salt Lake City, with engineering spread across North America and Europe.
SpeechEasy Upvotes
CassetteAi Upvotes
SpeechEasy Top Features
Accepts plain text or a web link as input and returns downloadable voice audio
Nearly a dozen high-definition synthetic voices, with more added regularly per the homepage
Starter plan is $0 and includes access to all voices plus core app features
Sign in and generate audio through beta1-app.speecheasyapp.com on desktop or mobile
Homepage pricing table lists 4 tiers: Starter, Content Creator, Marketer, and Enterprise
Privacy-first positioning with minimal personal data collection stated on the homepage
CassetteAi Top Features
30-second music sample renders in under 2 seconds at 44.1 kHz stereo
SFX generator produces up to 30 seconds of sound in roughly 1 second
Music pricing is $0.02 per output minute with 10 to 180 second durations
SFX pricing is a flat $0.01 per generation with loop-safe outputs
300M parameter music model with deterministic seeds for reproducible tracks
Same fal.subscribe() call shape for music, SFX, and upcoming TTS models
SpeechEasy Category
- Audio Generation
CassetteAi Category
- Audio Generation
SpeechEasy Pricing Type
- Freemium
CassetteAi Pricing Type
- Paid