SpeechEasy vs VALL-E
When comparing SpeechEasy vs VALL-E, which AI Audio Generation tool shines brighter? We look at pricing, alternatives, upvotes, features, reviews, and more.
In a comparison between SpeechEasy and VALL-E, which one comes out on top?
When we put SpeechEasy and VALL-E side by side, both being AI-powered audio generation tools, In the race for upvotes, SpeechEasy takes the trophy. The number of upvotes for SpeechEasy stands at 6, and for VALL-E it's 5.
Disagree with the result? Upvote your favorite tool and help it win!
SpeechEasy

What is SpeechEasy?
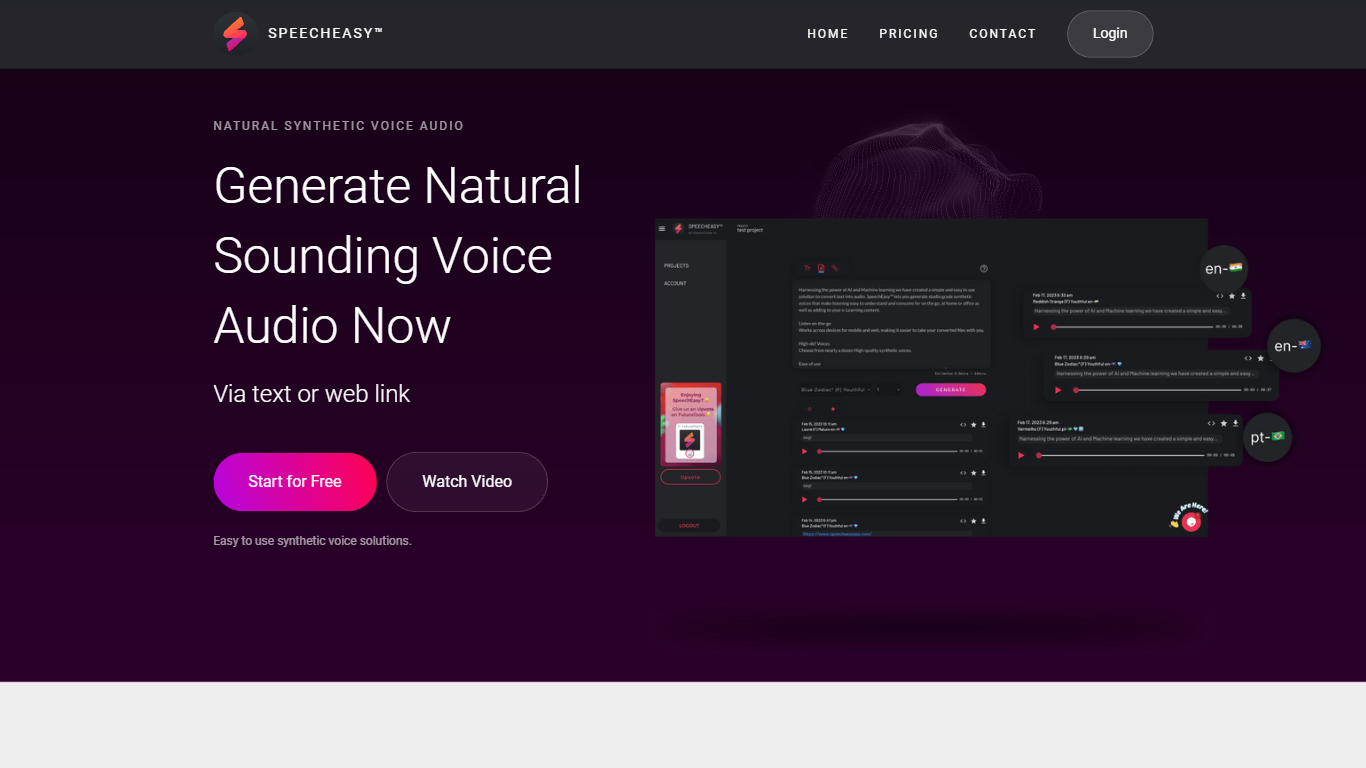
SpeechEasy turns written text or a pasted web link into studio-grade synthetic voice audio you can play on desktop or mobile. The marketing site pitches it for listening on the go, at home, or in the office, and for dropping narration into e-learning content without recording a human voice.
Where heavier voice editors pack timelines, SSML, and cloning workflows, SpeechEasy keeps the surface area small: pick a voice, feed it text or a URL, and export audio. The free Starter tier still unlocks the full voice library, which is unusual in a category that often gates premium voices behind paid plans. Paid upgrades route through an in-app Content Creator purchase, while a Marketer tier remains listed as coming soon.
Course builders, marketers on tight video deadlines, and publishers turning articles into listenable files are the clearest fits. The homepage also calls out audiobook-style publishing and stakeholder-ready marketing voiceovers as named use cases.
VALL-E
What is VALL-E?
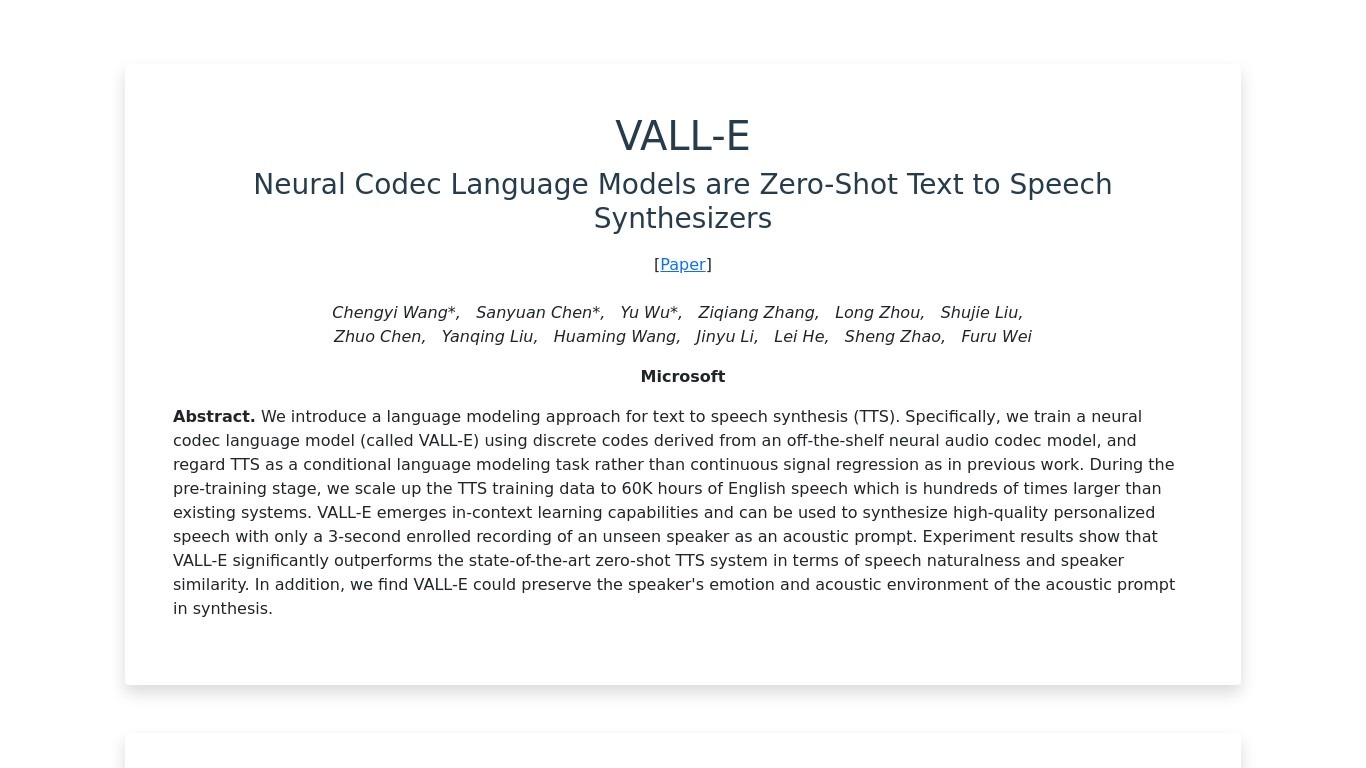
VALL-E is a Microsoft Research text-to-speech model that clones a speaker's voice from a short audio clip and generates new speech from text. It belongs to the audio generation category because it synthesizes natural speech rather than editing existing recordings. The project page hosts sample audio for the original VALL-E model and later variants in the same research family.
Most TTS systems regress continuous waveforms or mel-spectrograms directly. VALL-E instead treats speech as a conditional language modeling task over discrete codes from a neural audio codec. Microsoft trained it on about 60,000 hours of English speech, far larger than typical TTS datasets. A 3-second enrolled recording of an unseen speaker is enough to drive zero-shot synthesis, and the model can keep the emotion and room tone present in that prompt.
The VALL-E family grew beyond the first paper. VALL-E X handles cross-lingual zero-shot TTS, VALL-E R adds phoneme monotonic alignment for more stable speech generation, and VALL-E 2 pairs repetition-aware sampling with grouped code modeling to reach human parity on LibriSpeech and VCTK benchmarks. Related lines like MELLE, FELLE, and PALLE explore continuous mel tokens and hybrid autoregressive plus parallel decoding.
Researchers, speech engineers, and curious listeners use VALL-E to hear what large-scale codec language models can do before building their own pipelines. The public samples are research demos, not a hosted API you can plug into a product without separate licensing and ethics review.
SpeechEasy Upvotes
VALL-E Upvotes
SpeechEasy Top Features
Accepts plain text or a web link as input and returns downloadable voice audio
Nearly a dozen high-definition synthetic voices, with more added regularly per the homepage
Starter plan is $0 and includes access to all voices plus core app features
Sign in and generate audio through beta1-app.speecheasyapp.com on desktop or mobile
Homepage pricing table lists 4 tiers: Starter, Content Creator, Marketer, and Enterprise
Privacy-first positioning with minimal personal data collection stated on the homepage
VALL-E Top Features
Clones an unseen speaker from a 3-second enrolled audio prompt
Pre-trained on about 60,000 hours of English speech data
VALL-E 2 reports human parity on LibriSpeech and VCTK zero-shot benchmarks
Preserves speaker emotion and acoustic environment from the prompt clip
VALL-E X extends zero-shot synthesis to cross-lingual scenarios
Sample pages cover seven model lines including MELLE, FELLE, and PALLE
SpeechEasy Category
- Audio Generation
VALL-E Category
- Audio Generation
SpeechEasy Pricing Type
- Freemium
VALL-E Pricing Type
- Free