Last updated 09-01-2026
Category:
Reviews:
Join thousands of AI enthusiasts in the World of AI!
Omost
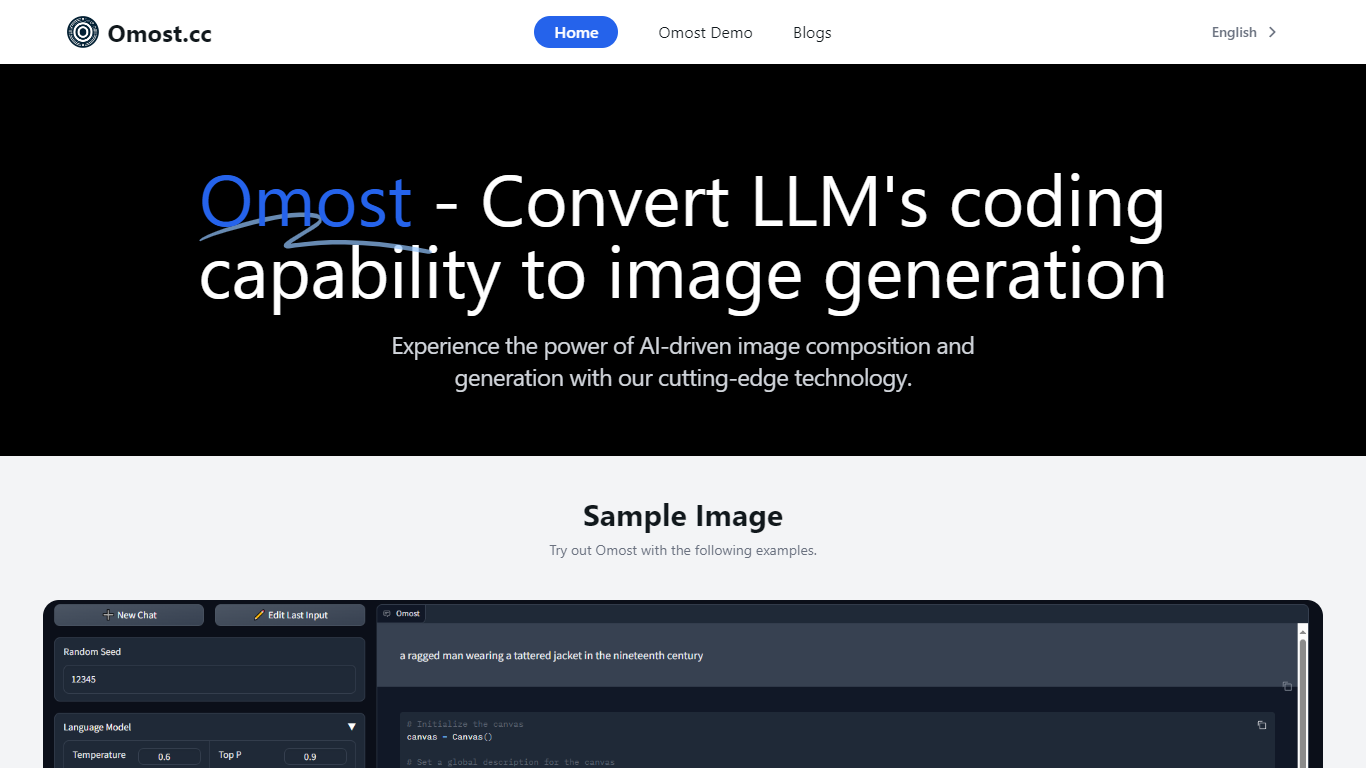
Turn a plain-language scene into region-aware image composition code, then render it through diffusion. Omost trains large language models to write Python that places subjects on a virtual Canvas with location, offset, area, depth, and HTML color hints before a bundled renderer paints the finished picture.
Most text-to-image tools send one prompt string to a diffusion model. Omost splits the job: an LLM outputs structured Canvas code with nine location slots, offset tweaks, and bounding-box sizes that map to 729 region proposals. The repo's baseline renderer uses attention score manipulation so each regional description gets guided diffusion, a different trade-off than encoding everything in a single CLIP pass.
Researchers and ML engineers experimenting with multi-subject layouts can run the Gradio app locally or try the official HuggingFace space. The README documents conversational editing, so you can swap subjects mid-session before hitting render. Training mixed Open-Images annotations, auto-labeled data, DPO compile checks, and a small GPT-4o tuning set across three Llama 3 and Phi-3 model families.
Three HuggingFace model families: omost-llama-3-8b, omost-dolphin-2.9-llama3-8b, and omost-phi-3-mini-128k
Local Gradio deploy needs about 8GB Nvidia VRAM with Python 3.10 and CUDA 12.1 PyTorch
Canvas API maps subjects to 729 region proposals via nine locations, offsets, and area sizes
Conversational editing swaps elements like changing a dragon to a dinosaur before render
Baseline renderer uses attention score manipulation for region-guided diffusion
Apache 2.0 open source with an official HuggingFace Space demo linked from the README
Open source under Apache 2.0 with full local deployment instructions on GitHub.
Region-aware Canvas code gives finer multi-subject control than a single text prompt.
Conversational editing lets you refine compositions before rendering.
Quantized model variants fit in 8GB VRAM without offloading.
Local setup requires an Nvidia GPU with at least 8GB VRAM.
The last main-branch commit was June 2024, so repository activity has slowed.
omost-phi-3-mini-128k quality degrades after about 8k tokens despite a 128k context label.
Is Omost free to use?
Yes. Omost is open source under the Apache 2.0 license on GitHub. You can clone the repository, run it locally, or use the official HuggingFace space linked from the README at no cost.
What hardware does Omost need for local runs?
Omost local deployment requires about 8GB of Nvidia VRAM. The README recommends Python 3.10, PyTorch with CUDA 12.1, and the pinned dependencies in requirements.txt. Quantized 4-bit models fit 8GB without offload.
Which LLM models does Omost support?
Omost provides three pretrained model families on HuggingFace: omost-llama-3-8b, omost-dolphin-2.9-llama3-8b, and omost-phi-3-mini-128k, each with quantized variants. The README recommends omost-llama-3-8b-4bits for most users.
Can I edit a scene after the initial prompt in Omost?
Yes. Omost supports conversational editing in the Gradio UI: you can ask the model to change specific Canvas elements, such as replacing a dragon with a dinosaur, then render the updated composition when you are satisfied.
How does Omost differ from a standard text-to-image prompt?
Instead of one prompt string, Omost generates structured Canvas code with separate global and local descriptions, spatial regions, and depth ordering. A custom diffusion renderer uses those regions to guide attention during image generation.
Where can I try Omost without installing it?
The Omost GitHub README links to an official HuggingFace space for browser-based demos. Local setup is also documented with conda, pip, and a gradio_app.py entry point.