FinetuneFast vs LiteLLM
In the battle of FinetuneFast vs LiteLLM, which AI Large Language Model (LLM) tool comes out on top? We compare reviews, pricing, alternatives, upvotes, features, and more.
Which one is better? FinetuneFast or LiteLLM?
Upon comparing FinetuneFast with LiteLLM, which are both AI-powered large language model (llm) tools, FinetuneFast is the clear winner in terms of upvotes. FinetuneFast has been upvoted 8 times by aitools.fyi users, and LiteLLM has been upvoted 6 times.
Not your cup of tea? Upvote your preferred tool and stir things up!
FinetuneFast

What is FinetuneFast?
FinetuneFast is a paid boilerplate kit for fine-tuning and deploying machine learning models. It bundles pre-configured training scripts, data loading pipelines, hyperparameter optimization, and deployment templates so developers can move from setup to production faster than building everything from scratch.
The package covers text-to-image, large language models, RAG applications, and related workflows. Included examples reference providers such as AWS Bedrock, Mistral AI, and OpenAI, along with templates for Flux-Schnell text-to-image, Fish-Speech text-to-speech, and retrieval-augmented generation.
After purchase, buyers receive access to GitHub repository materials with documentation. The All In plan adds Discord community access and lifetime updates. Founder Patrick built the product from hands-on ML engineering experience, including work on model training, inference APIs, and scalable infrastructure.
LiteLLM
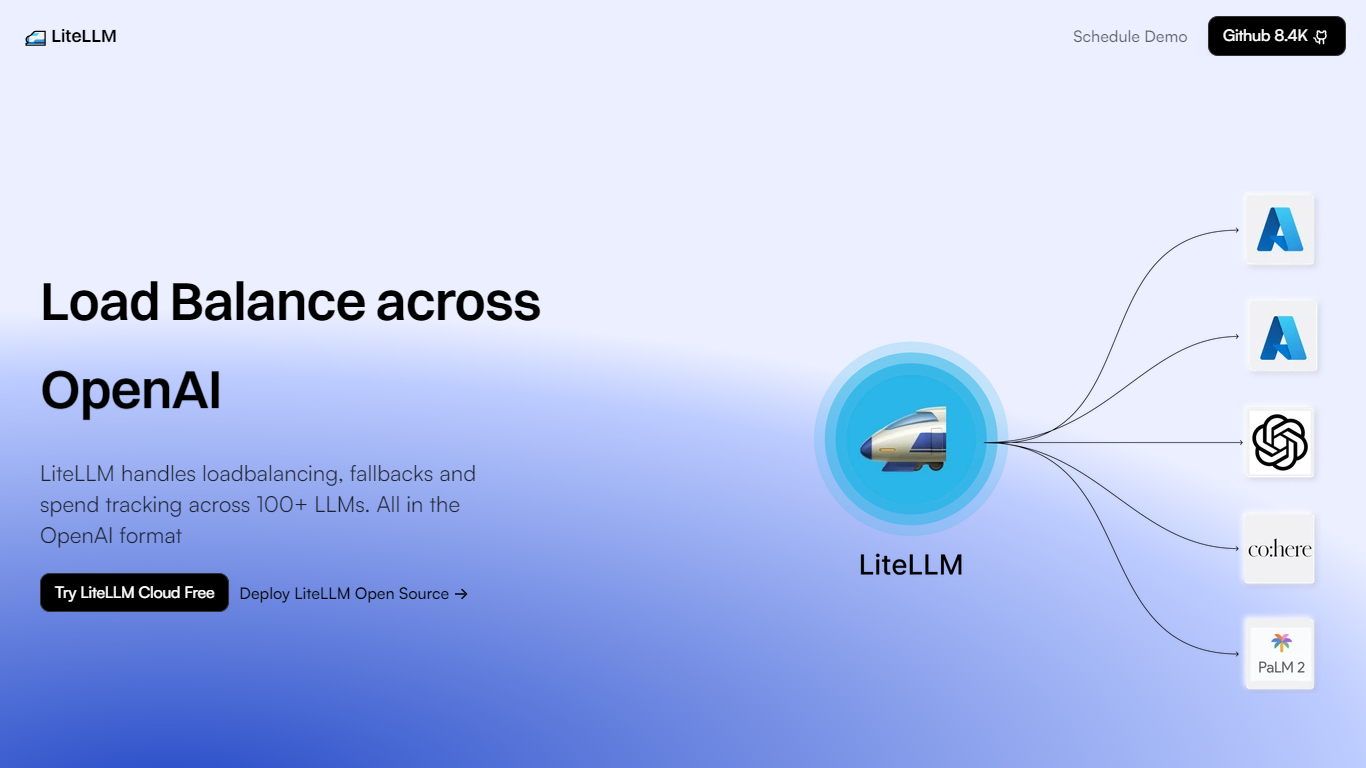
What is LiteLLM?
LiteLLM is a self-hosted AI gateway and LLM proxy that sits between your apps and model providers. You point clients at one OpenAI-compatible endpoint, and the gateway handles routing, logging, and spend controls across 140+ backends. Teams at Netflix, NVIDIA, and Okta use it to standardize model access without rebuilding every service when a provider changes.
Where hosted proxies bill per token and keep keys on their cloud, LiteLLM runs in your VPC or an air-gapped cluster under an MIT license. Budgets and RPM/TPM caps are hard stops, not alerts, so a leaked key or runaway job cannot keep spending after it hits the limit.
Platform and ML infrastructure teams reach for it when they need one front door for humans, agents, and batch jobs. The same gateway covers LLM calls, MCP servers, and agent workflows, with enterprise SSO, audit logs, and SLAs when rollout goes company-wide.
FinetuneFast Upvotes
LiteLLM Upvotes
FinetuneFast Top Features
Pre-configured training scripts with multi-GPU support and no-code fine-tuning options
Efficient data loading pipelines for preparing and organizing training datasets
Hyperparameter optimization tools to tune model performance
One-click deployment with auto-scaling infrastructure and generated API endpoints
Production-ready inference boilerplates, RAG examples, and AI SaaS starter templates
Model coverage includes Flux-Schnell, Mistral, OpenAI integrations, Fish-Speech TTS, and RAG workflows
LiteLLM Top Features
One OpenAI-compatible API routes requests to 140+ providers and 1,892 models
Hard budgets plus RPM and TPM limits per key, team, and org stop traffic at the cap
MIT-licensed self-hosted gateway with 240M+ Docker pulls and air-gapped deployment support
Rust AI Gateway adds 0.66 ms p99 latency at 2,800+ requests per second in published benchmarks
Built-in guardrails cover PII masking and prompt-injection checks via Presidio and Lakera
Virtual keys, spend tracking, and Prometheus metrics ship in the free open-source tier
FinetuneFast Category
- Large Language Model (LLM)
LiteLLM Category
- Large Language Model (LLM)
FinetuneFast Pricing Type
- Paid
LiteLLM Pricing Type
- Freemium