OneOver vs Falcon-40B on Hugging Face
In the clash of OneOver vs Falcon-40B on Hugging Face, which AI Large Language Model (LLM) tool emerges victorious? We assess reviews, pricing, alternatives, features, upvotes, and more.
When we put OneOver and Falcon-40B on Hugging Face head to head, which one emerges as the victor?
Let's take a closer look at OneOver and Falcon-40B on Hugging Face, both of which are AI-driven large language model (llm) tools, and see what sets them apart. Interestingly, both tools have managed to secure the same number of upvotes. You can help us determine the winner by casting your vote and tipping the scales in favor of one of the tools.
Think we got it wrong? Cast your vote and show us who's boss!
OneOver

What is OneOver?
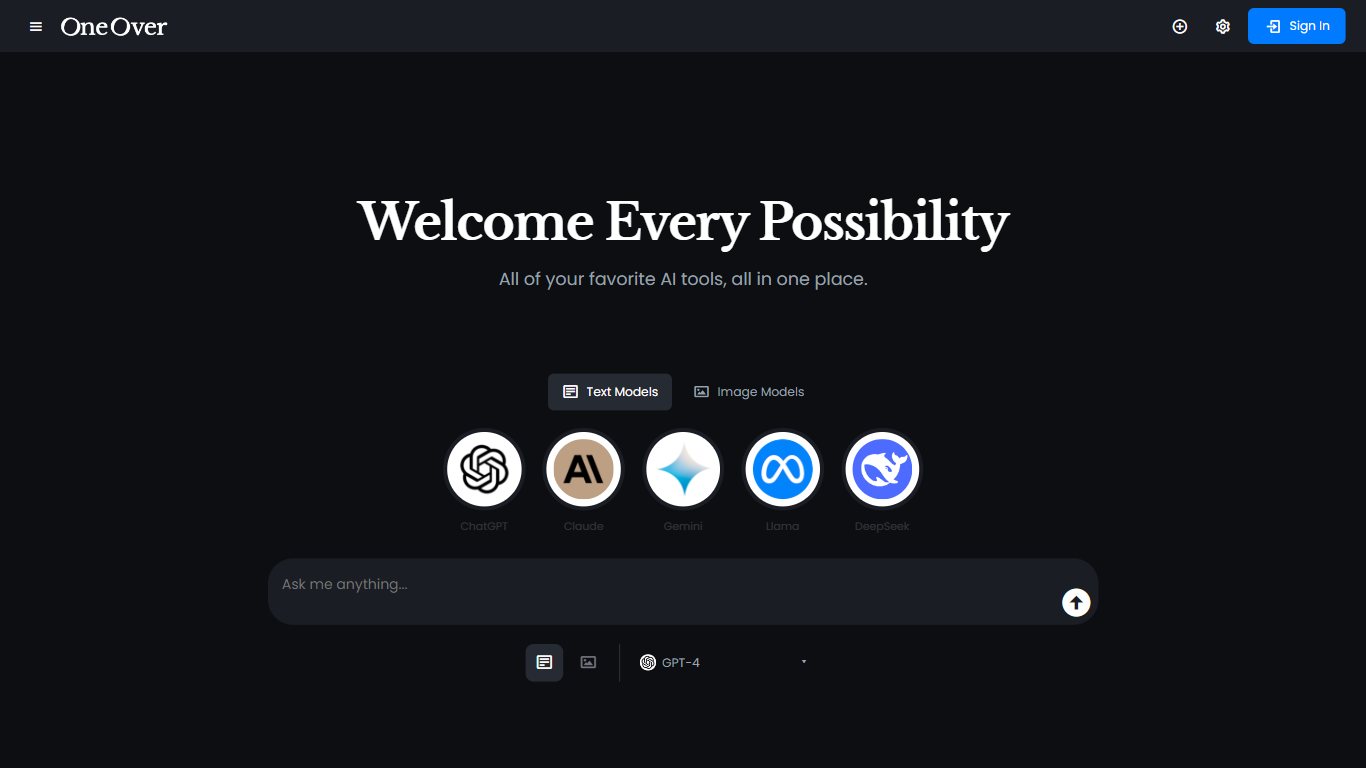
OneOver is a creative studio that puts multi-model chat, image generation, video, voice, and music in one browser workspace. You can run GPT, Claude, Gemini, Grok, and dozens of other models in a single thread, attach PDFs and images, flip on web search, and swap models without losing context. Guests get five chat messages before signup, and new accounts receive 50 one-time starter credits.
Where most tools make you pick one provider and buy separate subscriptions for images or video, OneOver routes everything through one shared credit balance. Subscription refills, plan bonuses, and pay-as-you-go packs all spend across chat, diffusion, video, speech, music, and playground mini apps. Switching from GPT-5.4 Nano to Claude Opus 5 is a dropdown change in the same conversation, not a copy-paste hop between sites.
Creators and marketers use OneOver to draft copy, iterate visuals, and turn prompts or photos into short clips from one library. Developers can hit the same model routes through a REST API with streaming support. Pro and Studio also ship seat-based team plans that pool monthly credits with member soft limits and one invoice.
Falcon-40B on Hugging Face
What is Falcon-40B on Hugging Face?
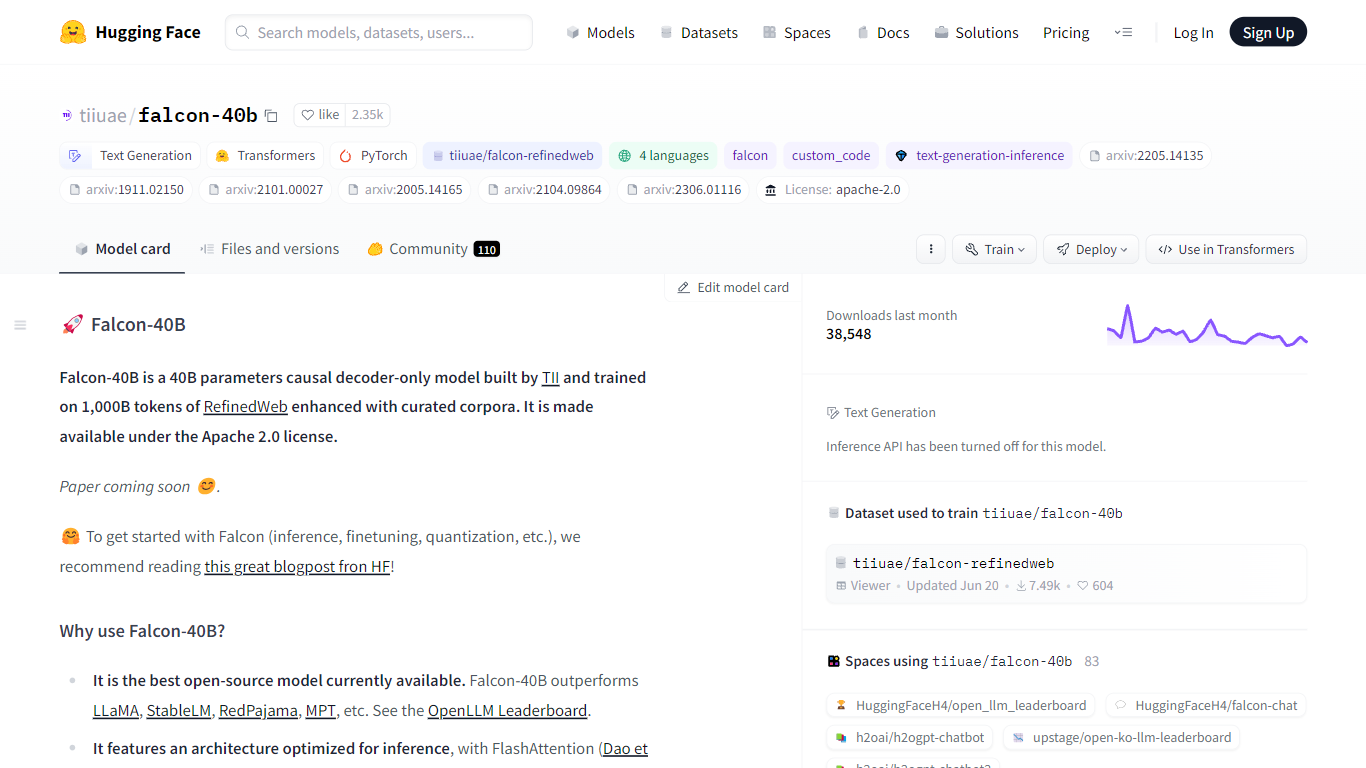
Falcon-40B on Hugging Face is a 40-billion-parameter causal decoder-only language model from the Technology Innovation Institute (TII), hosted as open weights on the Hugging Face Hub. You download the model and run it locally or on your own GPU cluster with Transformers, vLLM, SGLang, or quantized builds for Ollama and llama.cpp. It predicts the next token on a 2,048-token context window and ships as a raw pretrained checkpoint, not a chat-ready assistant.
Most open models at this size lean on heavily curated training mixes like The Pile. Falcon-40B was trained on 1,000 billion tokens drawn mostly from RefinedWeb, TII's filtered web crawl, with smaller slices of books, code, conversations, and technical papers. The architecture adds multiquery attention and FlashAttention on top of a GPT-3-style decoder, which TII tuned specifically for faster inference rather than chasing the widest possible task coverage out of the box.
Researchers and ML engineers reach for it as a finetuning base under the Apache 2.0 license, which allows commercial use without royalties. Running full-precision inference needs roughly 85 to 100 GB of GPU memory, so most production teams either quantize the weights or move to the smaller Falcon-7B sibling before deploying.
OneOver Upvotes
Falcon-40B on Hugging Face Upvotes
OneOver Top Features
Switch between GPT-5.6 Sol, Claude Opus 5, Gemini 3.6 Flash, and Grok 4.6 in one thread without losing context
Pro includes 1,400 credits per month (1,000 base plus 400 bonus) for chat, images, and short video work
Text-to-speech and text-to-music generators sit beside image and video studios in the same credit pool
Pay-as-you-go packs start at $5 for 500 credits that never expire and stack with subscription balances
REST API covers chat, image generation, and usage metering with streaming and one-field model swaps
Ten playground mini apps include Meme Generator, Upscaler, and Homework Helper with costs from 1 credit
Falcon-40B on Hugging Face Top Features
40 billion parameters trained on 1,000B tokens, 75% from the RefinedWeb crawl
Apache 2.0 license permits commercial use and redistribution without royalties
60-layer architecture with multiquery attention, FlashAttention, and 2,048-token context
Load via Transformers, vLLM, SGLang, or Docker with trust_remote_code=True
Primary languages: English, German, Spanish, and French, plus limited support for 6 more European languages
Quantized builds available for Ollama, llama.cpp, LM Studio, and Jan local apps
OneOver Category
- Large Language Model (LLM)
Falcon-40B on Hugging Face Category
- Large Language Model (LLM)
OneOver Pricing Type
- Freemium
Falcon-40B on Hugging Face Pricing Type
- Free