
Last updated 08-03-2026
Category:
Reviews:
Join thousands of AI enthusiasts in the World of AI!
StyleDrop
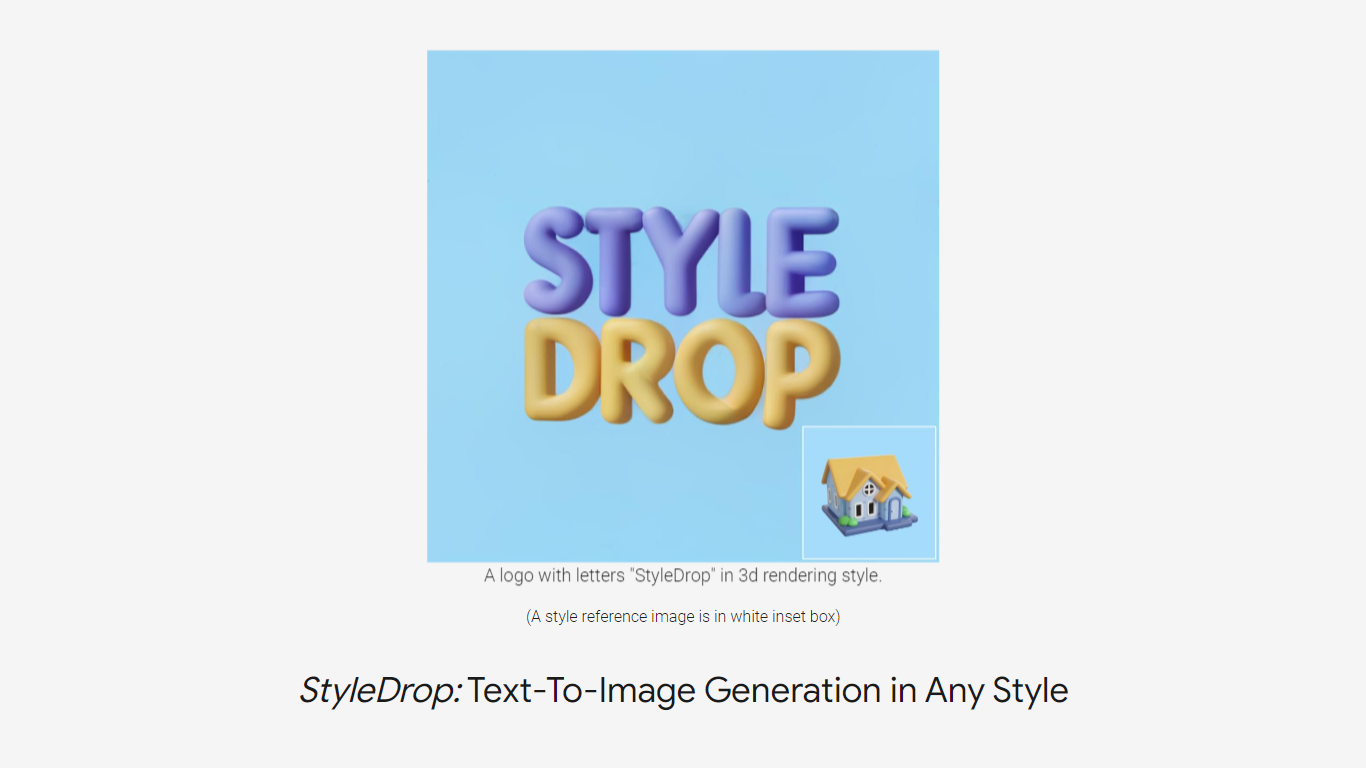
StyleDrop generates text-to-image outputs that match a specific visual style from as few as one reference image. This Google Research method fine-tunes less than 1% of the Muse vision transformer parameters through adapter tuning, then appends a natural-language style descriptor (like "in melting golden 3D rendering style") to your content prompt at generation time. It captures color schemes, shading, design patterns, and both local and global visual effects.
DreamBooth and Textual Inversion need multiple images and heavy fine-tuning to lock in a look. StyleDrop targets style alone: one reference image is enough, and the paper reports it outperforms those methods on Muse, Imagen, and Stable Diffusion backbones for style fidelity. Google also adapted the technique into a custom style model on Vertex AI for brand prototyping.
Graphic designers, art directors, and researchers studying controllable image generation are the natural audience. The project page hosts demos and comparisons, but StyleDrop itself is a research release rather than a standalone consumer app with signup or pricing.
Learns a new visual style by fine-tuning less than 1% of Muse model parameters
Works from a single reference image specifying color, shading, and design patterns
Iterative training with human or automated feedback improves style fidelity over rounds
Outperforms DreamBooth and Textual Inversion on style-tuning benchmarks in the paper
Combines with DreamBooth to render a custom subject in a custom style
Adapted into a Vertex AI custom style model for brand asset prototyping
Captures nuanced styles from a single reference image, not a folder of examples.
Parameter-efficient adapter tuning keeps training lightweight on Muse.
Paper-backed results showing gains over DreamBooth and Textual Inversion for style tasks.
Research demo only; no self-serve consumer app or API on the project page.
Enterprise access requires Google Cloud Vertex AI, which is a separate paid product.
Style tuning quality depends on the Muse backbone, not diffusion models like Stable Diffusion.
What is StyleDrop?
StyleDrop is a Google Research text-to-image method that generates images matching a user-provided visual style. It builds on the Muse generative vision transformer and uses adapter tuning to learn styles from as few as one reference image.
Is StyleDrop free to use?
StyleDrop is a research project with a public demo page at styledrop.github.io. It is not a commercial product with paid tiers. Google adapted the technique into Vertex AI for enterprise use, which has its own cloud pricing.
How does StyleDrop differ from DreamBooth?
StyleDrop focuses on capturing a visual style from a reference image, while DreamBooth personalizes a model on a specific subject. StyleDrop fine-tunes less than 1% of Muse parameters and can combine with DreamBooth to place a custom subject in a custom style.
How many images does StyleDrop need?
StyleDrop can deliver strong results from a single reference image that defines the desired style. The method uses iterative training with feedback to improve quality over multiple rounds, but the initial style capture needs only one example.
Who created StyleDrop?
StyleDrop was developed by Google Research researchers including Kihyuk Sohn, Nataniel Ruiz, Kimin Lee, and Dilip Krishnan. The paper was presented as a NeurIPS 2023 poster and is available on arXiv as 2306.00983.
What model does StyleDrop use?
StyleDrop is built on Muse, a discrete-token text-to-image generative vision transformer. It uses adapter tuning to efficiently learn new styles without retraining the full model, which keeps the trainable parameter count under 1%.