LiteLLM vs ggml.ai
Explore the showdown between LiteLLM vs ggml.ai and find out which AI Large Language Model (LLM) tool wins. We analyze upvotes, features, reviews, pricing, alternatives, and more.
In a face-off between LiteLLM and ggml.ai, which one takes the crown?
When we contrast LiteLLM with ggml.ai, both of which are exceptional AI-operated large language model (llm) tools, and place them side by side, we can spot several crucial similarities and divergences. The users have made their preference clear, ggml.ai leads in upvotes. ggml.ai has 7 upvotes, and LiteLLM has 6 upvotes.
Don't agree with the result? Cast your vote and be a part of the decision-making process!
LiteLLM

What is LiteLLM?
LiteLLM is a self-hosted AI gateway and LLM proxy that sits between your apps and model providers. You point clients at one OpenAI-compatible endpoint, and the gateway handles routing, logging, and spend controls across 140+ backends. Teams at Netflix, NVIDIA, and Okta use it to standardize model access without rebuilding every service when a provider changes.
Where hosted proxies bill per token and keep keys on their cloud, LiteLLM runs in your VPC or an air-gapped cluster under an MIT license. Budgets and RPM/TPM caps are hard stops, not alerts, so a leaked key or runaway job cannot keep spending after it hits the limit.
Platform and ML infrastructure teams reach for it when they need one front door for humans, agents, and batch jobs. The same gateway covers LLM calls, MCP servers, and agent workflows, with enterprise SSO, audit logs, and SLAs when rollout goes company-wide.
ggml.ai
What is ggml.ai?
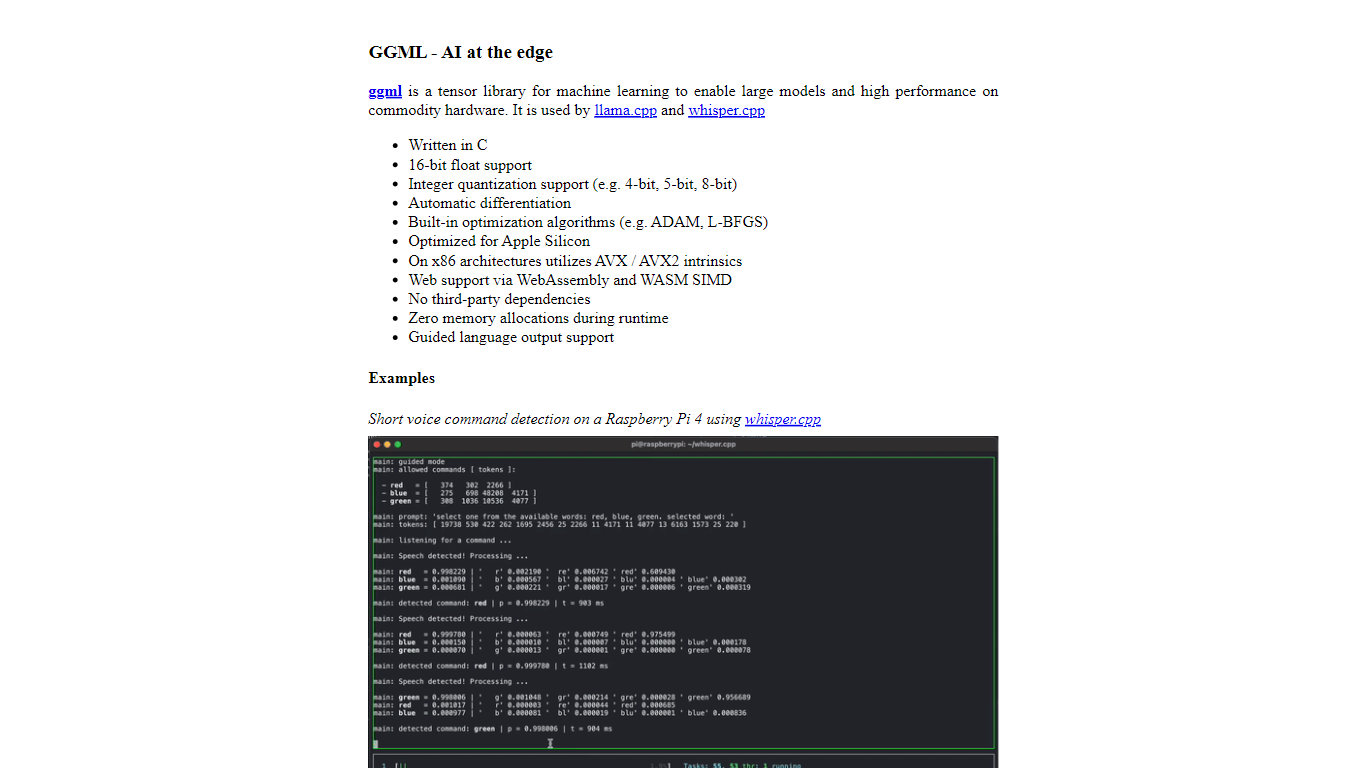
ggml runs large language and speech models on everyday CPUs and GPUs through a compact C tensor library built for on-device inference. ML engineers and app developers adopt it via llama.cpp and whisper.cpp when they want LLaMA or Whisper workloads without cloud-only dependencies.
Frameworks like PyTorch optimize for training clusters and heavy runtimes. ggml keeps the core library minimal with zero runtime memory allocations, no third-party dependencies, and integer quantization so llama.cpp can serve Meta LLaMA weights on laptops and Apple Silicon.
The ggml.ai company was founded in 2023 by Georgi Gerganov to support the library and was acquired by Hugging Face in 2026. The core ggml project stays MIT licensed with open development on GitHub.
LiteLLM Upvotes
ggml.ai Upvotes
LiteLLM Top Features
One OpenAI-compatible API routes requests to 140+ providers and 1,892 models
Hard budgets plus RPM and TPM limits per key, team, and org stop traffic at the cap
MIT-licensed self-hosted gateway with 240M+ Docker pulls and air-gapped deployment support
Rust AI Gateway adds 0.66 ms p99 latency at 2,800+ requests per second in published benchmarks
Built-in guardrails cover PII masking and prompt-injection checks via Presidio and Lakera
Virtual keys, spend tracking, and Prometheus metrics ship in the free open-source tier
ggml.ai Top Features
Powers llama.cpp for Meta LLaMA inference and whisper.cpp for OpenAI Whisper speech models
Written in C with zero runtime memory allocations during inference
Integer quantization support for smaller models on commodity hardware
No third-party dependencies in the core tensor library
Cross-platform low-level implementation with broad hardware support
MIT licensed open-core library with public development on GitHub
LiteLLM Category
- Large Language Model (LLM)
ggml.ai Category
- Large Language Model (LLM)
LiteLLM Pricing Type
- Freemium
ggml.ai Pricing Type
- Free