
Last updated 07-30-2026
Category:
Reviews:
Join thousands of AI enthusiasts in the World of AI!
ALBERT
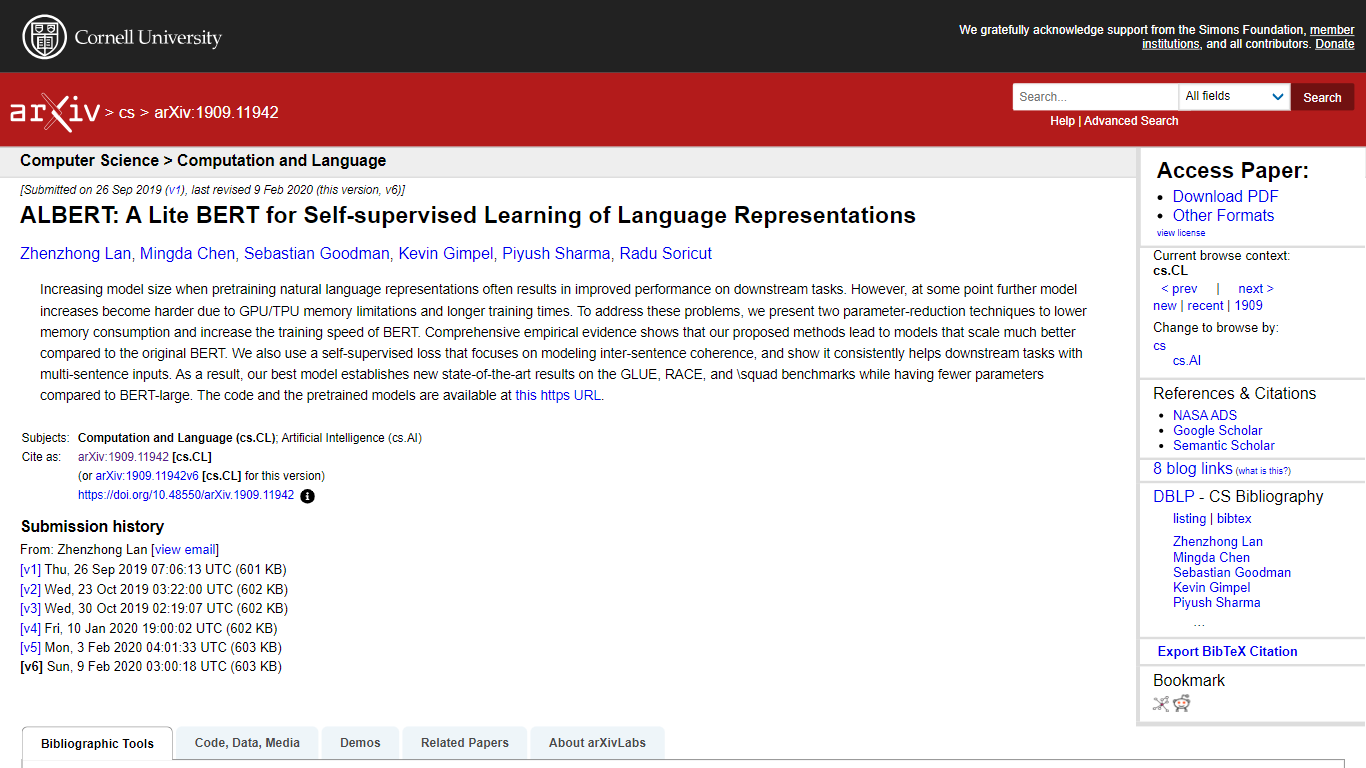
ALBERT is an open source language model from Google Research that shrinks BERT's parameter count while matching or beating its benchmark scores. The name stands for A Lite BERT, and the architecture uses two tricks: factorized embedding parameterization splits the vocabulary matrix into smaller pieces, and cross-layer parameter sharing reuses weights across transformer layers.
Where BERT-large hits GPU memory walls during pretraining, ALBERT scales to larger hidden sizes with fewer total parameters. It also swaps BERT's next-sentence prediction loss for sentence-order prediction (SOP), which the authors found more effective for multi-sentence downstream tasks. The best ALBERT configuration set records on GLUE (89.4), RACE (89.4% accuracy), and SQuAD 2.0 (92.2 F1) at the time of publication.
Pretrained models and training code ship free on GitHub and load through Hugging Face Transformers. Researchers and NLP engineers use ALBERT when they need BERT-level performance on limited hardware or want a lighter model for fine-tuning on classification, question answering, and token-level tasks.
Factorized embedding parameterization reduces memory vs standard BERT vocabulary matrices
Cross-layer parameter sharing cuts learnable weights across transformer layers
Sentence-order prediction (SOP) loss replaces BERT's next-sentence prediction
89.4% accuracy on RACE and 92.2 F1 on SQuAD 2.0 benchmark results
Pretrained models and code available on GitHub and Hugging Face Transformers
Trains larger configurations with less GPU memory than BERT.
Open source with free pretrained checkpoints on GitHub.
Strong benchmark results on GLUE, RACE, and SQuAD.
Native support in Hugging Face Transformers library.
Sentence-order prediction improves multi-sentence tasks.
Published in 2019; newer models like RoBERTa and DeBERTa often outperform it.
Requires ML infrastructure for training and fine-tuning.
No managed API or hosted service; you run models yourself.
Smaller default embedding size (128 vs BERT's 768) may limit some use cases.
What is ALBERT?
ALBERT (A Lite BERT) is an open source language model from Google Research published in 2019. It uses parameter-reduction techniques to train larger BERT-style models with less GPU memory while maintaining benchmark performance.
How much does ALBERT cost?
ALBERT is free and open source. Pretrained models and training code are available on GitHub at google-research/ALBERT with no license fees. You only pay for your own compute resources when training or running inference.
How does ALBERT differ from BERT?
ALBERT uses factorized embedding parameterization and cross-layer parameter sharing to reduce parameters compared to BERT. It also replaces BERT's next-sentence prediction with sentence-order prediction for better multi-sentence task performance.
Where can I download ALBERT pretrained models?
ALBERT pretrained models are available on the Google Research GitHub repository at github.com/google-research/ALBERT. Hugging Face Transformers also hosts ALBERT checkpoints with ready-to-use model classes.
What benchmarks did ALBERT achieve?
ALBERT achieved top benchmark scores on GLUE (89.4), RACE (89.4% accuracy), and SQuAD 2.0 (92.2 F1) when published in 2019, with fewer parameters than BERT-large.
What tasks can ALBERT be used for?
ALBERT supports masked language modeling, sentence classification, multiple choice, token classification, and question answering. Hugging Face provides AlbertForMaskedLM, AlbertForSequenceClassification, and other task-specific model heads.